
Model formats and compatibility: what a weights file has to declare
A weights file is not the model: format, architecture and tokenizer must all line up.
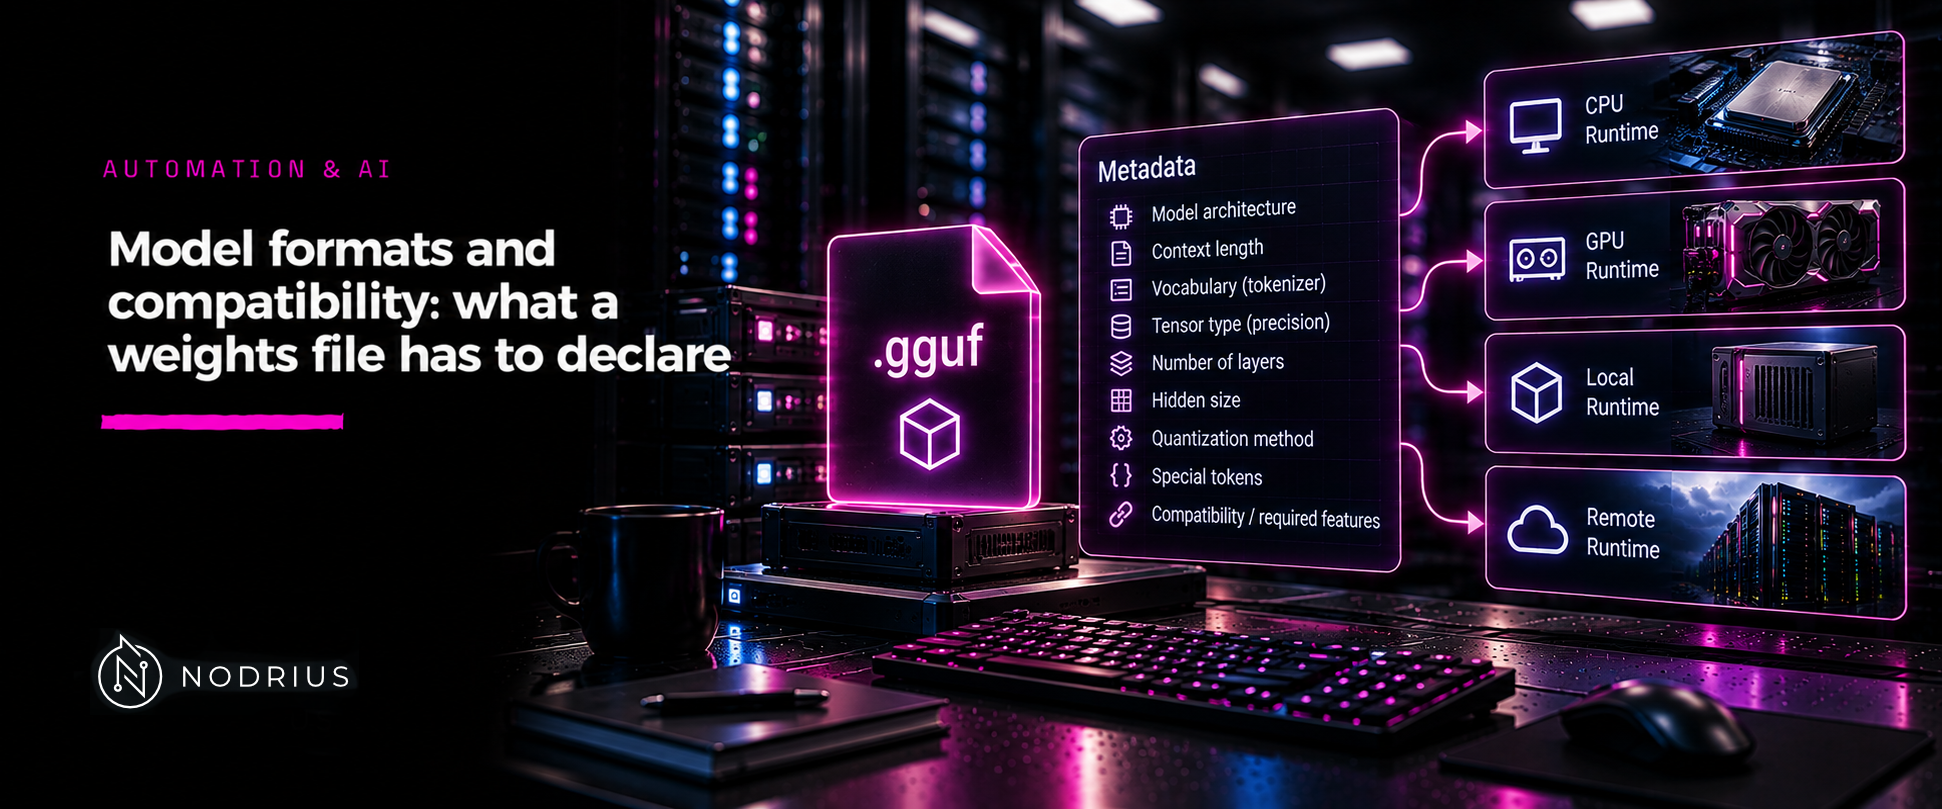
Downloading a model leaves you with a directory of tensors and a few configuration files. Nothing in the download tells you whether an inference engine can load it, and a model that loads successfully is not thereby a model that behaves as its authors intended. Four things have to line up before a weights file becomes a working model:
- the file format the runtime can read;
- the architecture the runtime implements;
- the tokenizer and configuration that define the contract between text and tensors;
- the quantization type of the tensors that are stored.
Only the first is visible in the file name. The other three are what “compatibility” actually means.
The formats you will meet
- safetensors — “a new simple format for storing tensors safely (as opposed to pickle) and that is still fast (zero-copy)”. A model is usually split into several shards with an index file that names them; the format is designed so a process can load part of the tensors rather than all of them, which matters when the weights are spread across devices.
- GGUF — “a single-file format used to store models for inference with GGML, containing the model metadata and tensors”. The specification describes it as “a binary format that is designed for fast loading and saving of models”, and as “designed to be unambiguous by containing all the information needed to load a model” and “designed to be extensible, so that new information can be added to models without breaking compatibility”.
- Legacy pickle checkpoints (
.bin,.ckpt) — the older format that safetensors was introduced to replace. The contrast matters more than the history: a pickle is a serialised Python object graph, so reading one is not a pure data operation, whereas safetensors was designed to be loaded safely. - Framework-native directories — a
config.json, a tokenizer definition and one or more weight files, which is what “the model” means when an engine says it supports Hugging Face models.
Why the format is a security decision, not only a technical one
A downloaded model is an artefact from a repository you do not control. OWASP’s LLM03 Supply Chain entry lists “Vulnerable Pre-Trained Model” — models as binary black boxes whose contents cannot be inspected — and “Weak Model Provenance”: “Currently there are no strong provenance assurances in published models. Model Cards and associated documentation provide model information and relied upon users, but they offer no guarantees on the origin of the model.” An attacker who compromises a repository account, or creates a convincing imitation, therefore inherits the trust your pipeline places in a download. Choosing a format that cannot execute code on load removes one class of harm before any other control is applied.
What “compatible” does not mean
“The engine supports GGUF” does not mean it supports this file. GGUF is a container, and the
quantization type is a property of the tensors inside it; the specification enumerates them, for instance
GGML_TYPE_Q2_K = 10, GGML_TYPE_Q4_K = 12, GGML_TYPE_Q6_K = 14, GGML_TYPE_IQ4_NL = 20,
GGML_TYPE_BF16 = 30. A runtime may read the container and reject or dequantise a type it does not
implement.
A file that loads is not a file whose tokenizer matches. Weights determine the computation; the tokenizer determines what the model is looking at. A model loaded with the wrong tokenizer produces fluent-looking text built on a wrong interpretation of the input — the failure is silent, which is why the configuration files belong to the model and travel with it.
The size in the file name is a convention, not a measurement. The GGUF naming convention asks for at
least BaseName, SizeLabel and Version, and the specification gives a regular expression to validate it,
with a stated reason: “it is easy for Encoding to be mistaken as a FineTune if Version is omitted.”
A file named Mixtral-8x7B-v0.1-KQ2.gguf declares, by convention, model name, expert count, parameter
count, version and weight encoding — and a sharded file declares its position, as in
Grok-100B-v1.0-Q4_0-00003-of-00009.gguf.
general.file_type is a hint about the majority of the tensors, not a guarantee about all of them:
the spec calls it “an enumerated value describing the type of the majority of the tensors in the file.
Optional; can be inferred from the tensor types.”
The check that has to happen before the model is trusted
- Format the engine reads — and, for GGUF, whether the quantization type is implemented rather than merely recognised.
- Architecture implemented by the engine, at the version you installed.
- Tokenizer and configuration that came with the same revision of the weights, not a similar one.
- Provenance: which repository, which account, which revision, and whether the download can be verified afterwards.
- A run — loading is a claim about compatibility, and generating the output you expect is the check.
Level and prerequisites. L2 — operational: enough to decide whether a weights file can be used, and what has to be verified before it is. It is not a conversion tutorial and does not tell you how to produce GGUF files; that belongs to Progetti. The L1 sheets on tokens and tokenizers and on the model/runtime boundary provide the vocabulary.
Where to go next
- Automation & AI — the macro-area this sheet belongs to.
- Model behaviour — the node this sheet sits in.
References
- Hugging Face — Safetensors documentation; GGUF documentation — the two formats’ own descriptions.
- ggml-org — GGUF specification — file structure, naming convention, quantization type enumeration and
general.file_type. - Hugging Face — Quantization overview — the list of quantization families and their hardware support.
- OWASP — Top 10 for LLM Applications (2025), LLM03 Supply Chain — vulnerable pre-trained models and weak model provenance.