
Articles
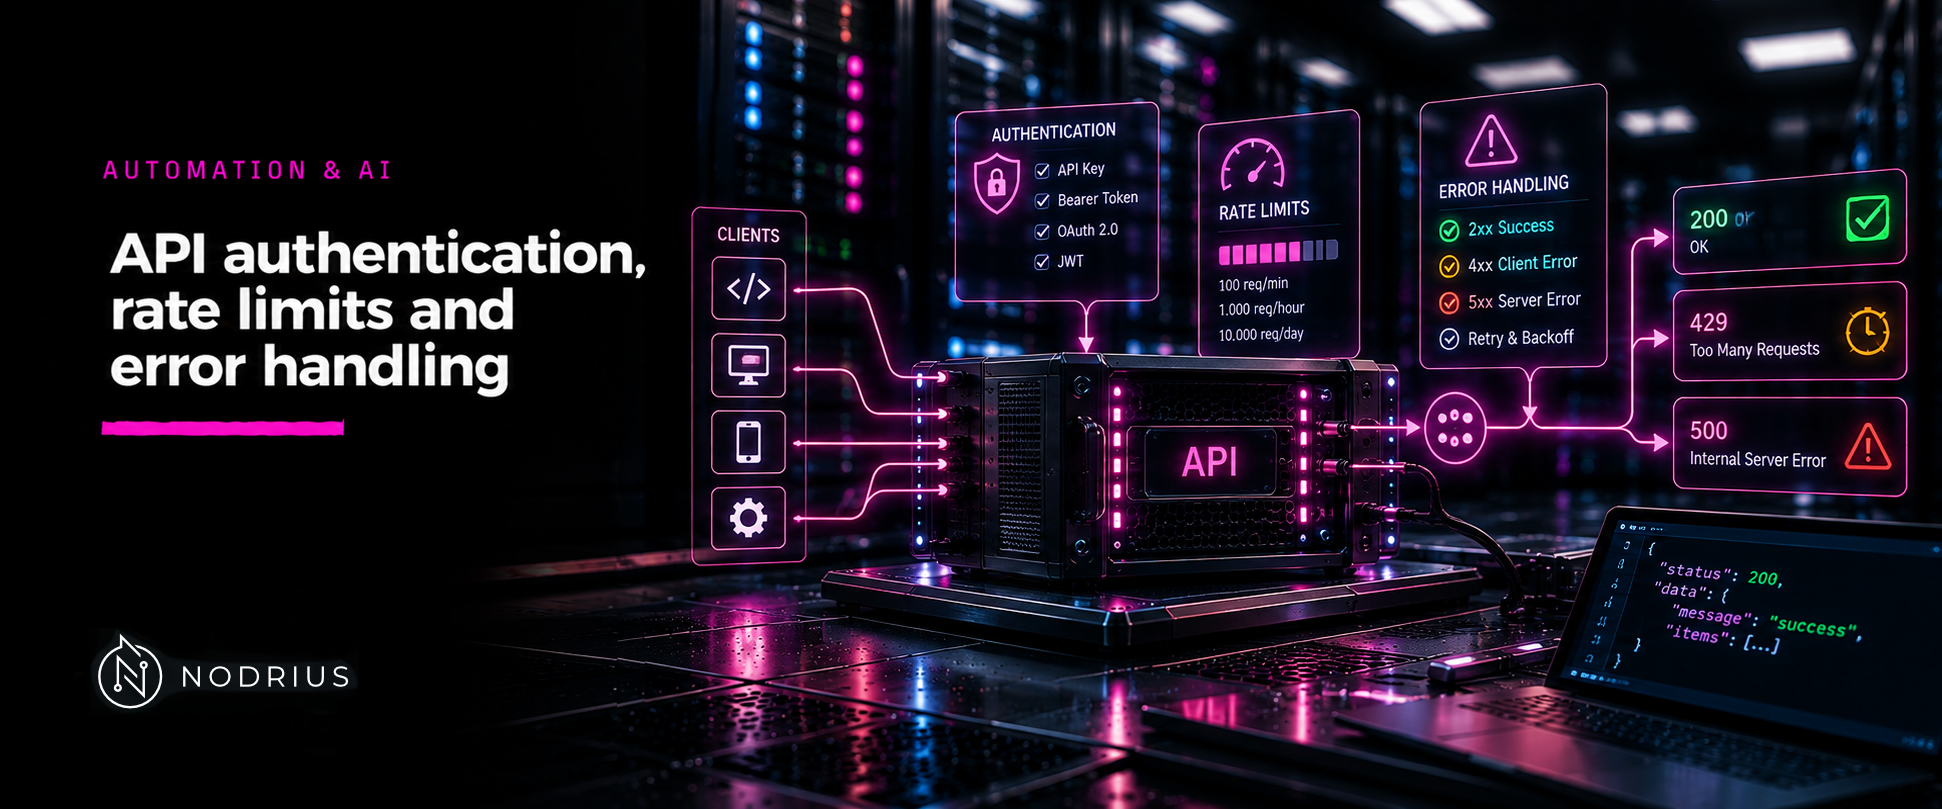
API authentication, rate limits and error handling
An endpoint refuses a request for three different reasons; the response says which.
Scripting, local inference, infrastructure and AI security.
An endpoint refuses a request for three different reasons; the response says which.
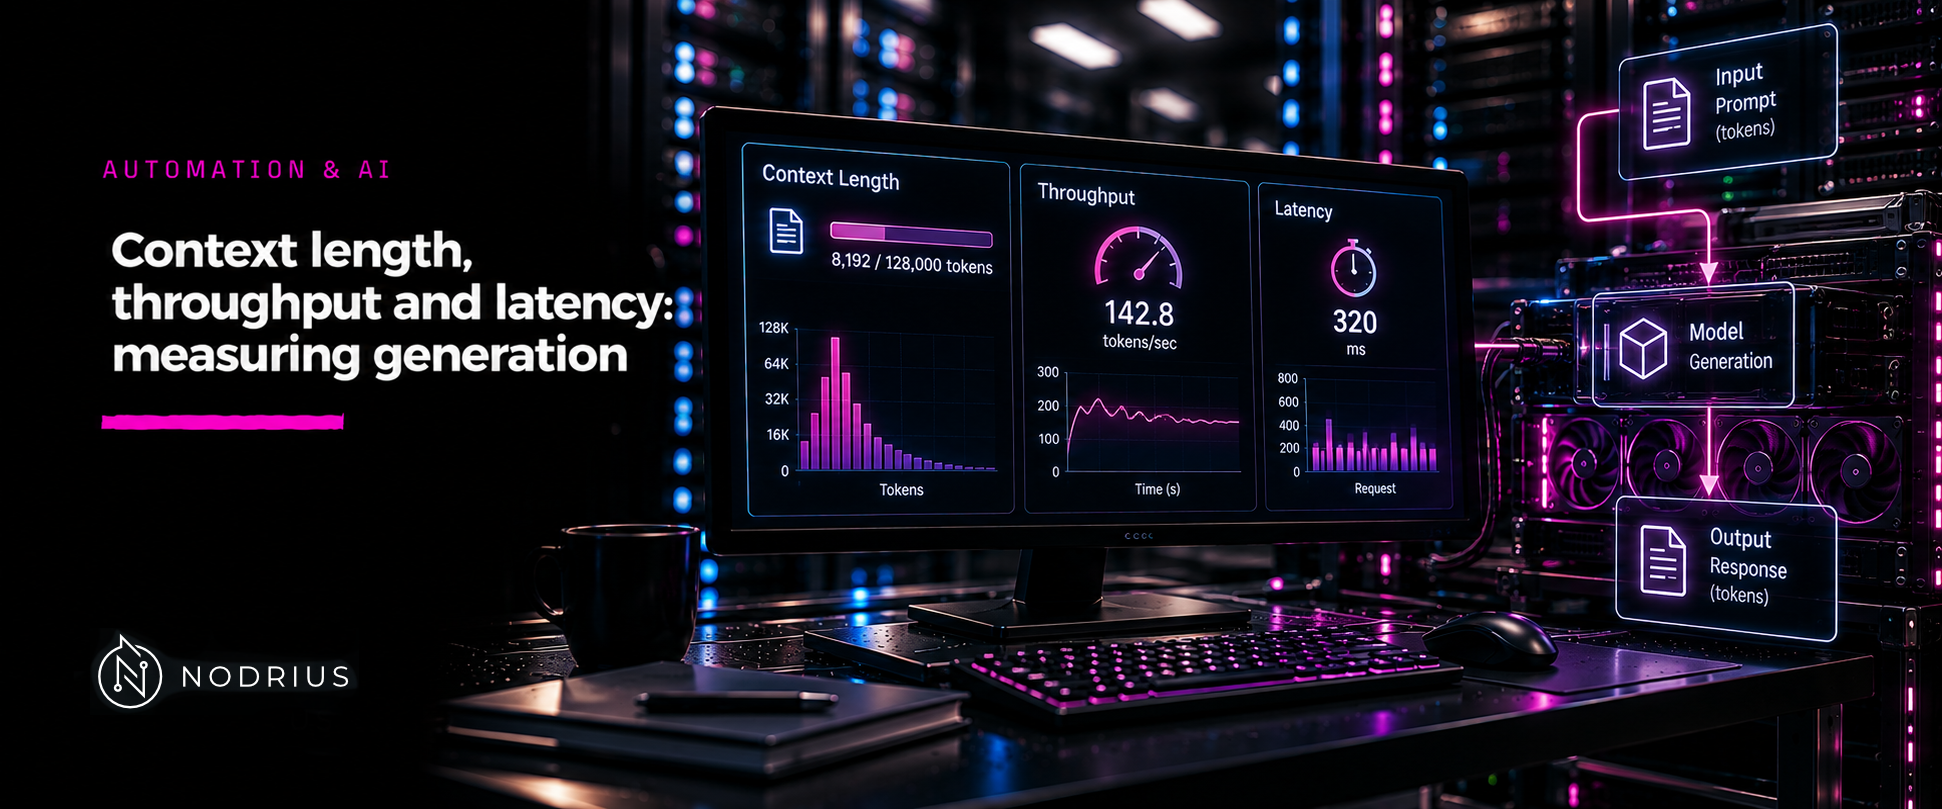
Four numbers describe a generation; none of them means anything without its conditions.
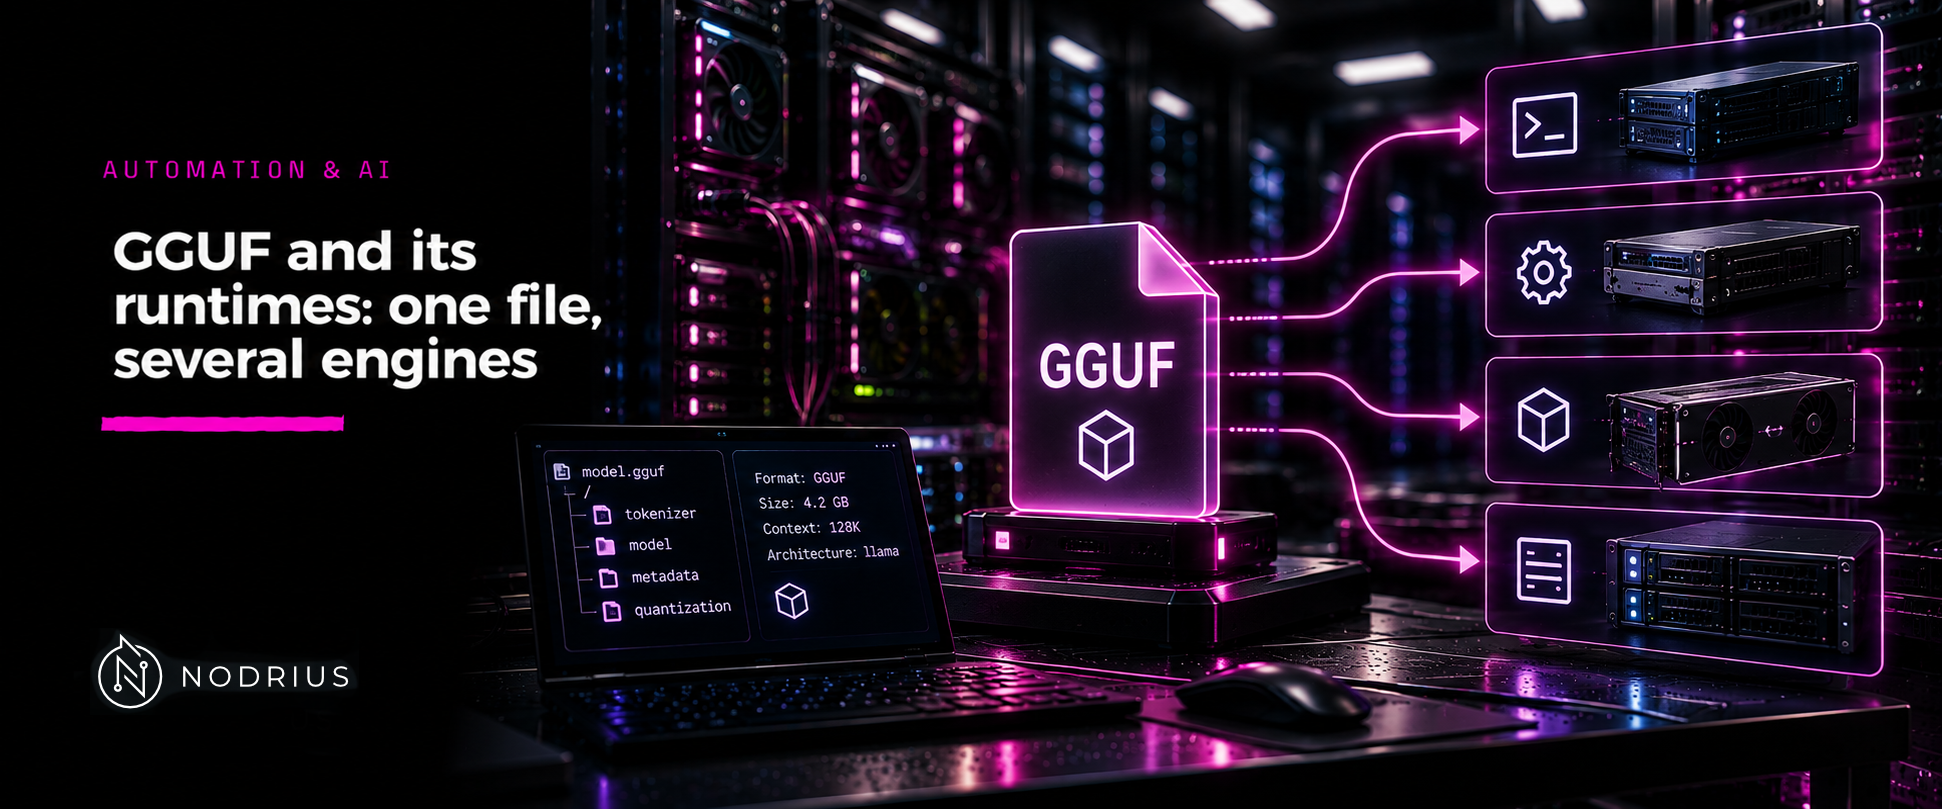
GGUF is a container; which engine reads it, and how, is a separate question.
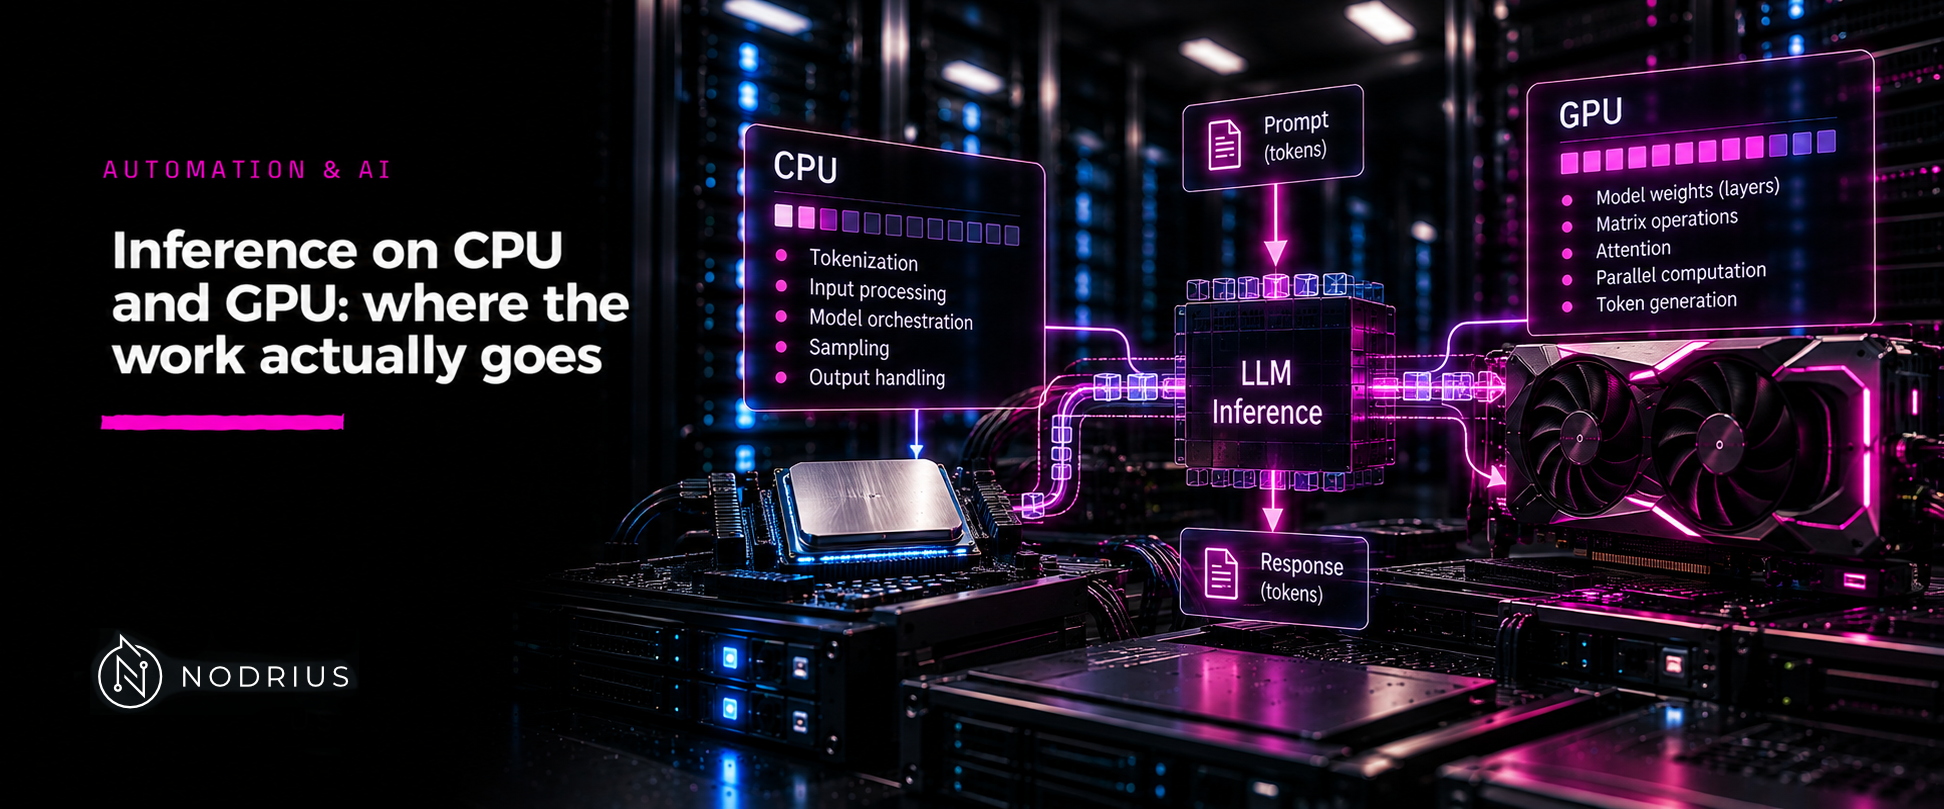
The same model runs on a CPU, a GPU or both; what changes is where the work is done.
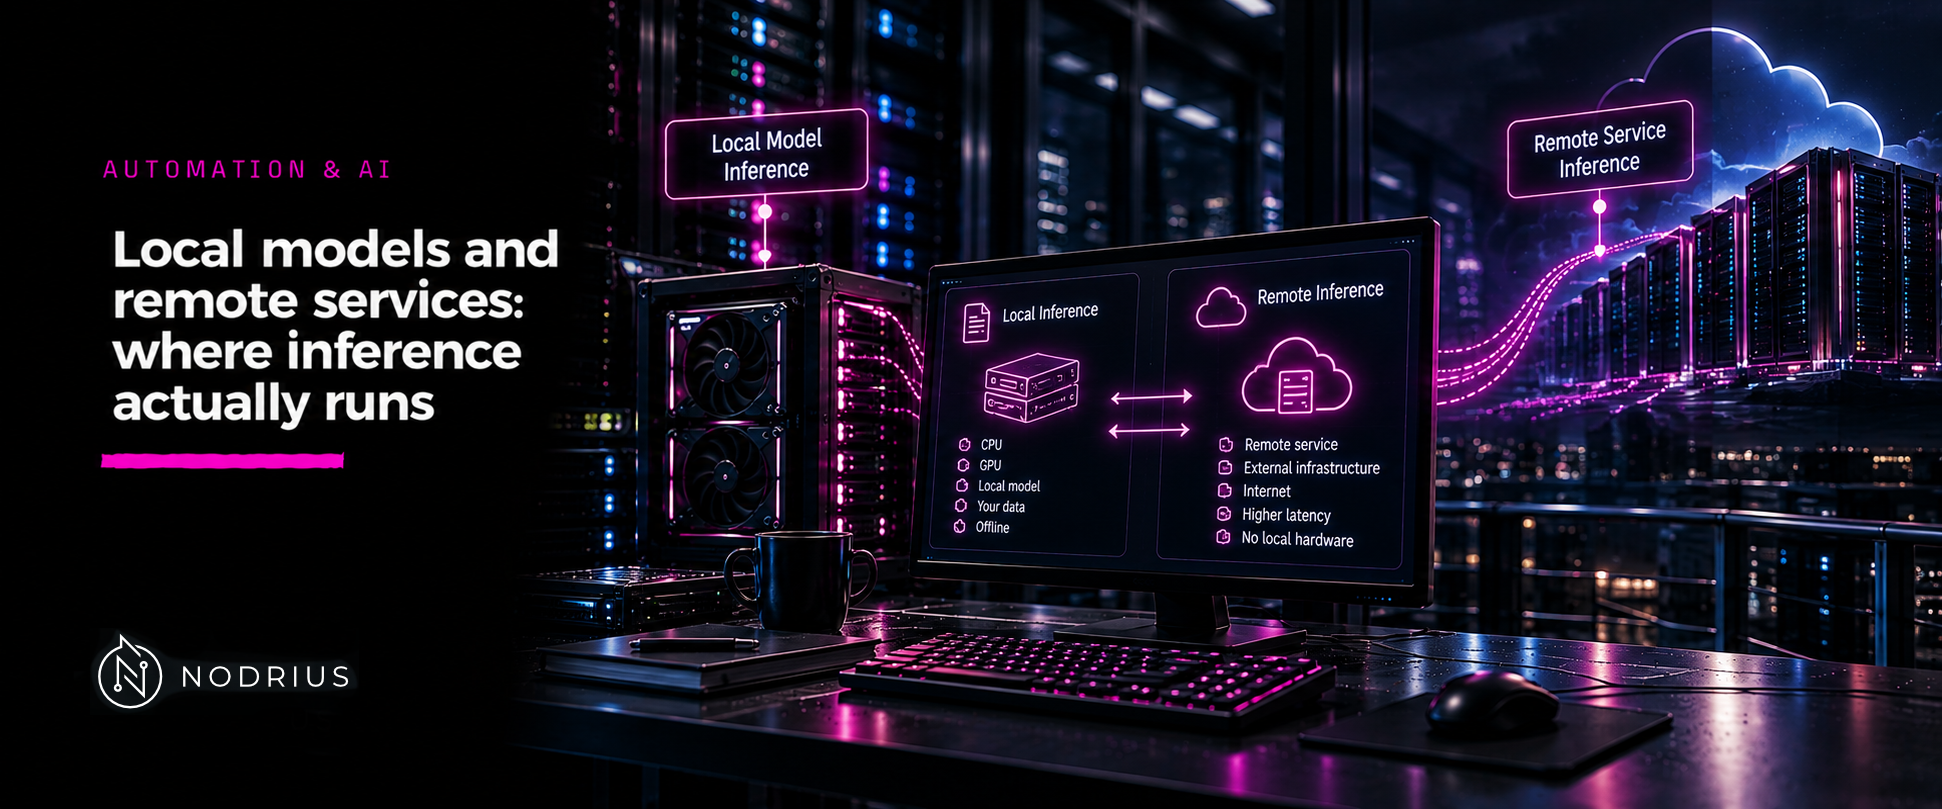
Where the weights sit decides who operates what, and what leaves your machine.
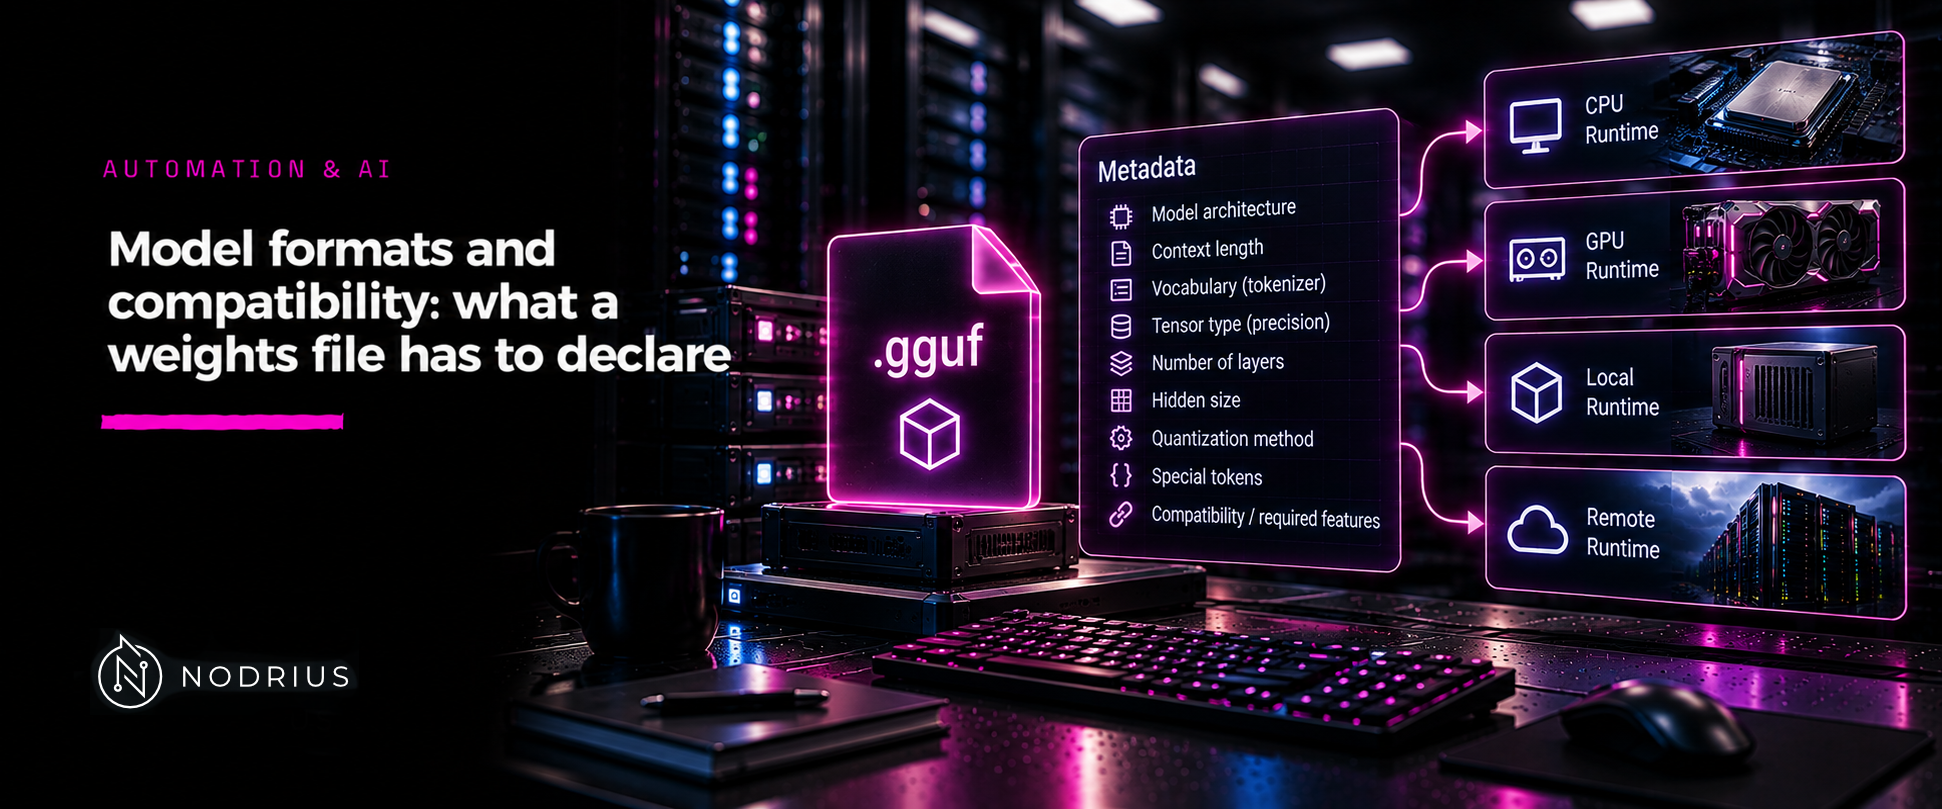
A weights file is not the model: format, architecture and tokenizer must all line up.
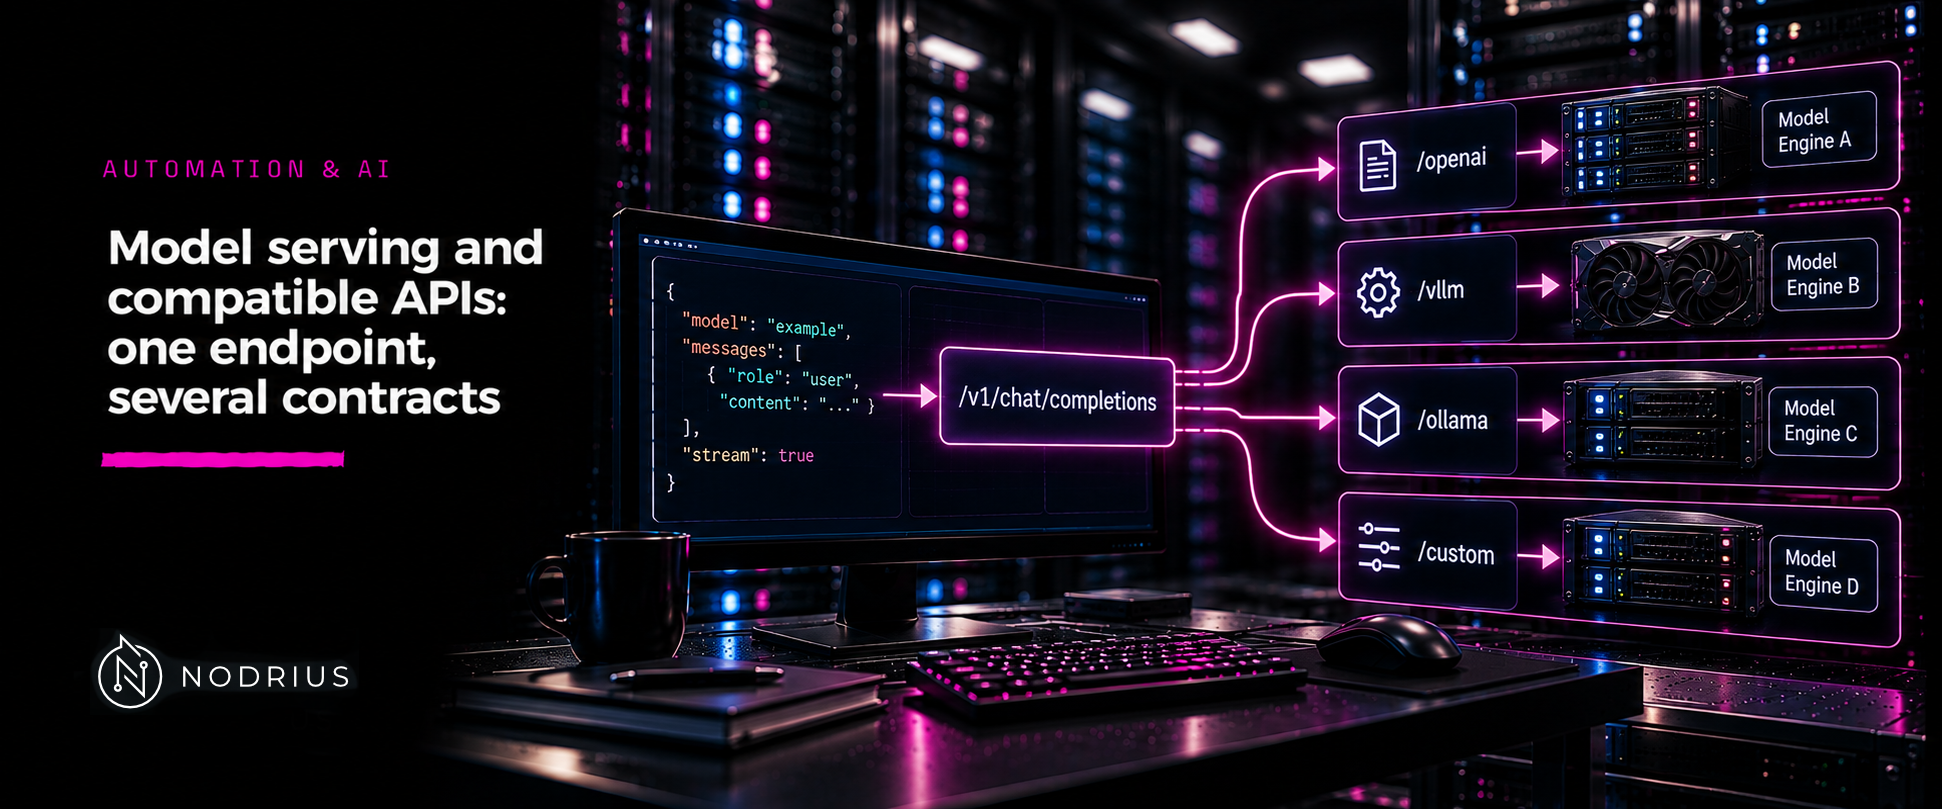
A serving engine adds a queue, a lifecycle and an API surface to a weights file.
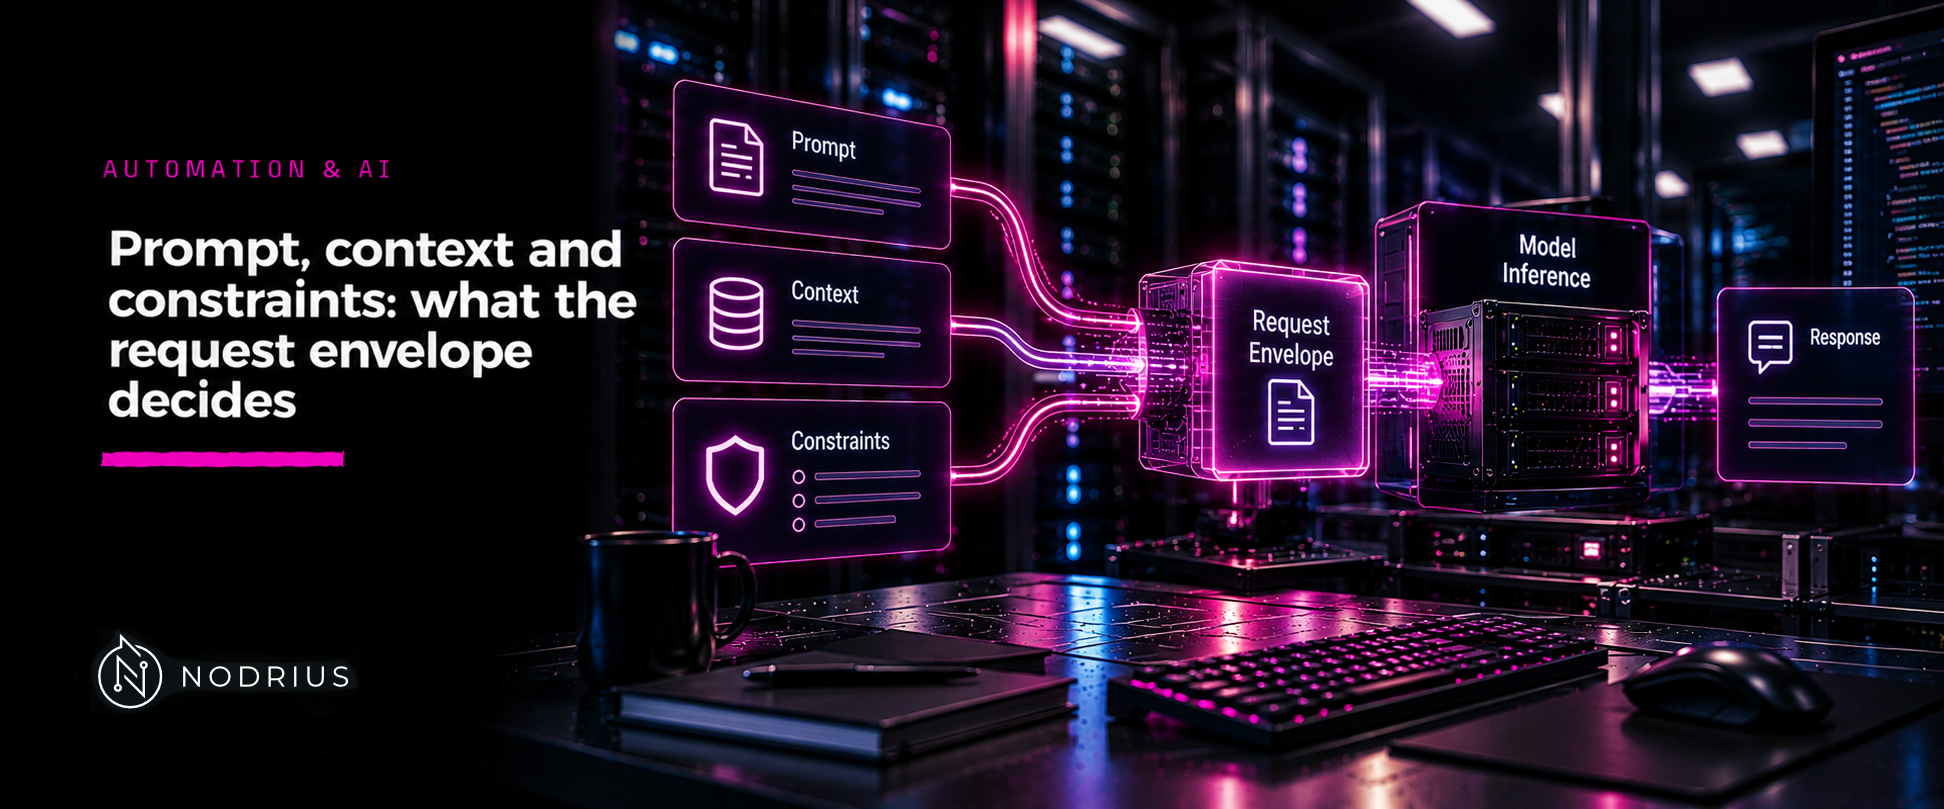
The model sees what the envelope builds: template, budget and stopping conditions.
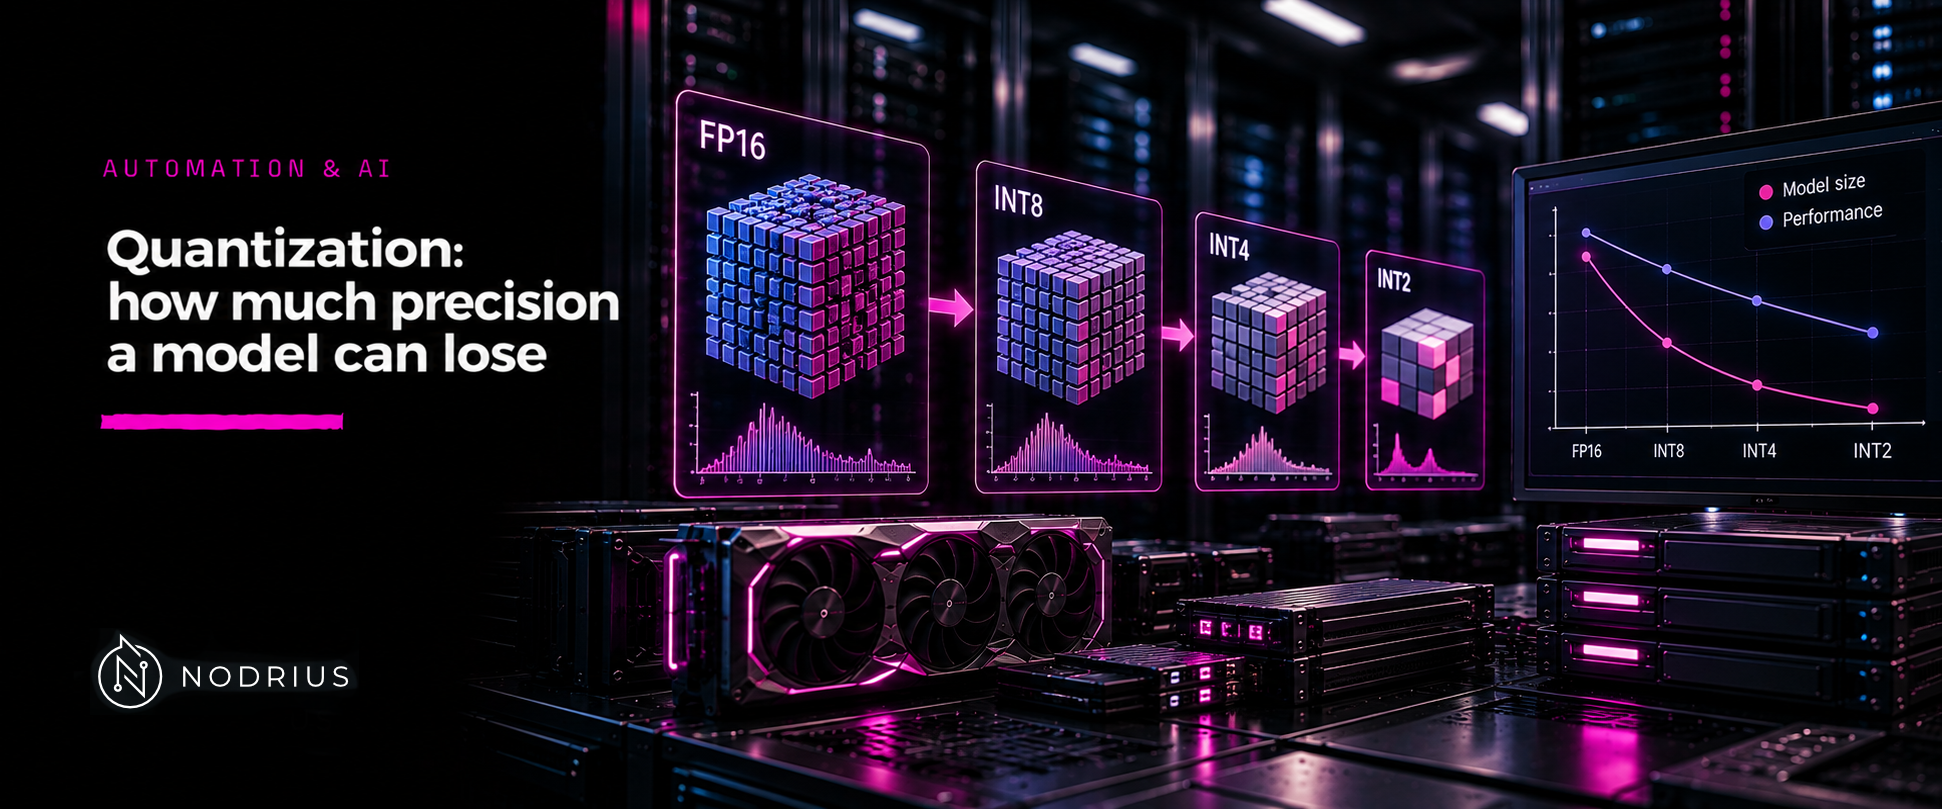
Fewer bits per weight save memory; what that costs in quality must be measured.
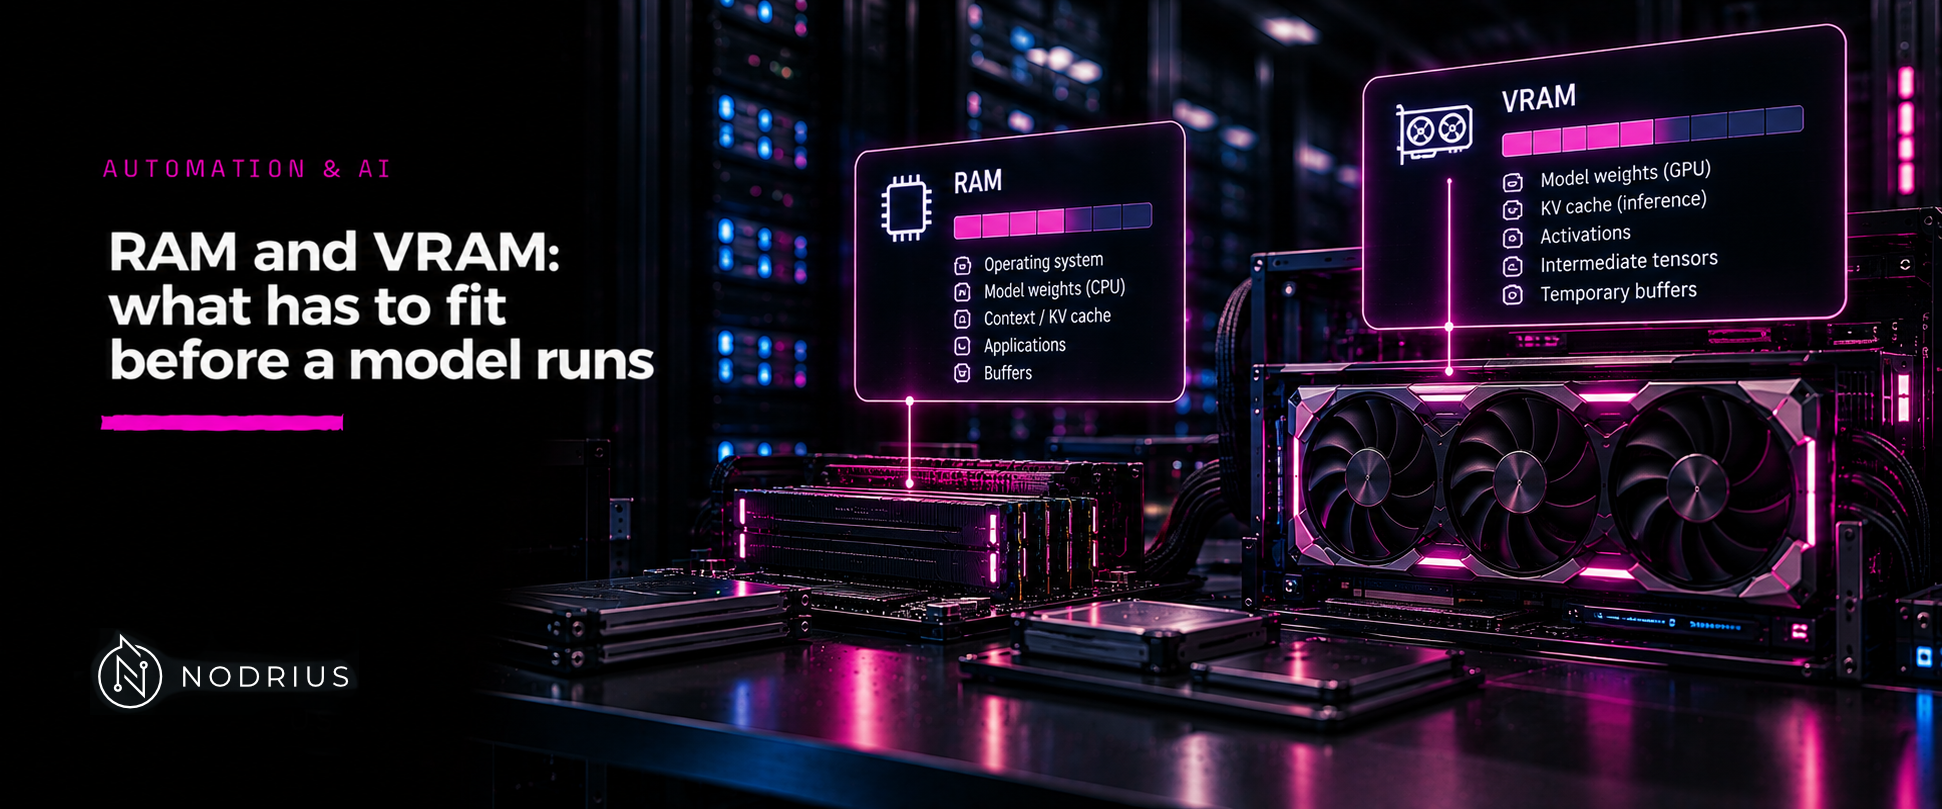
Weights, KV cache and working memory compete for the same pool; fit is arithmetic first.
Two families of sensitive material: the credentials you use and the content you send.
Streaming changes when you know; idempotency decides whether you may ask again.
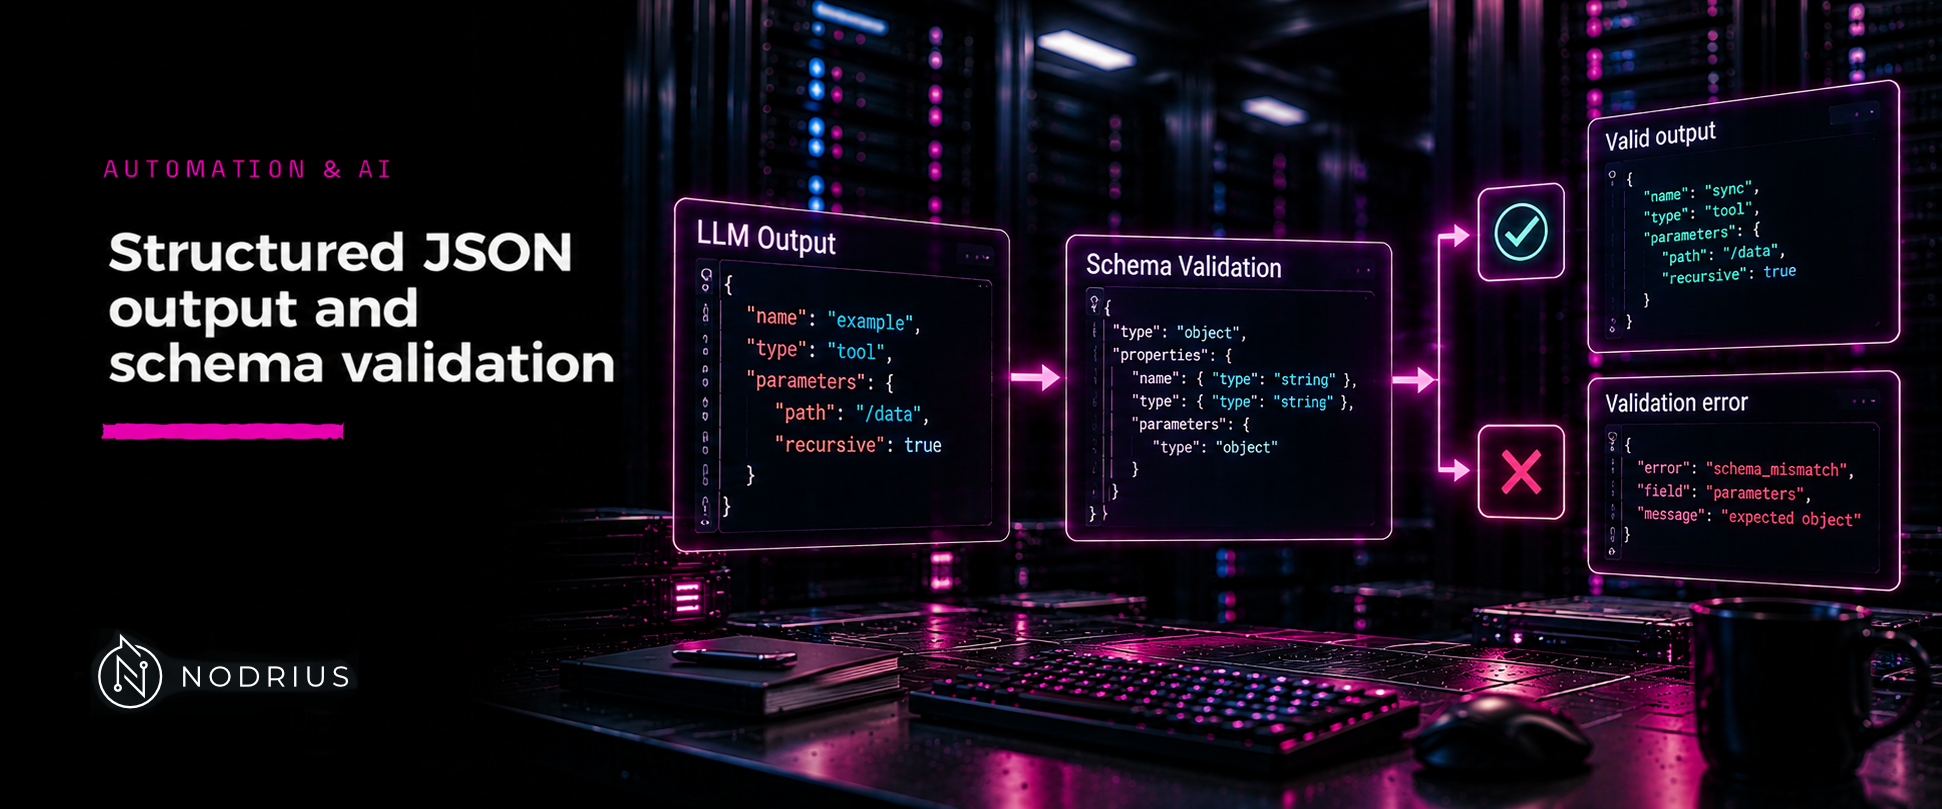
Asking for JSON and constraining the decoder to JSON are two different guarantees.
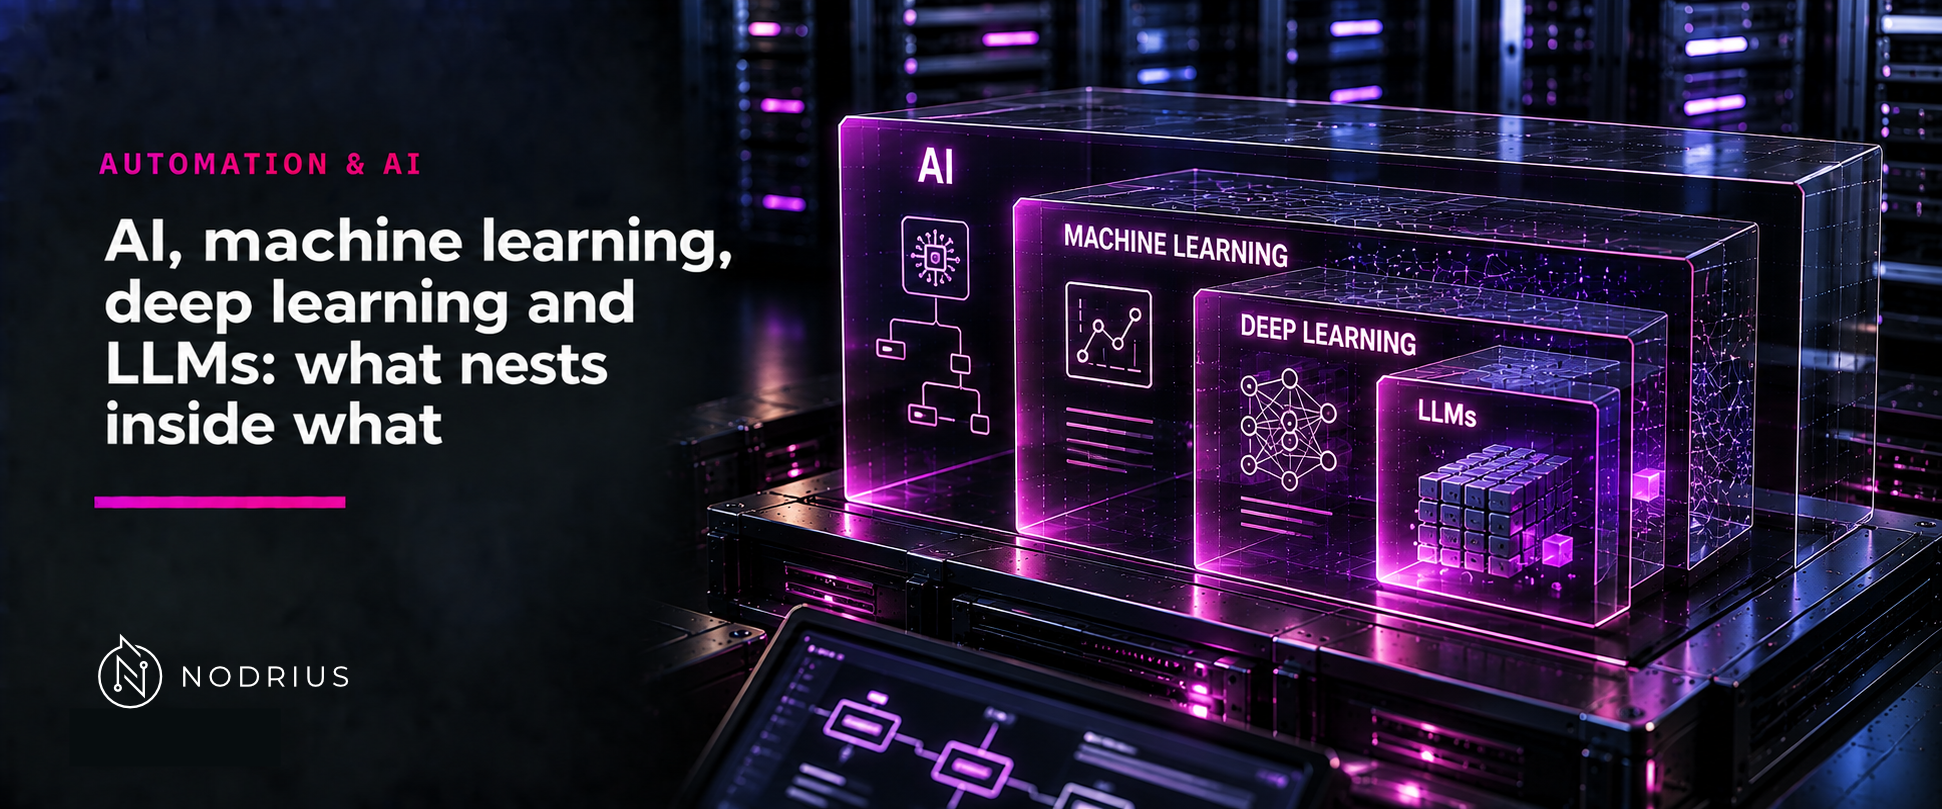
How AI, machine learning, deep learning and LLMs nest — and what each term does not imply.
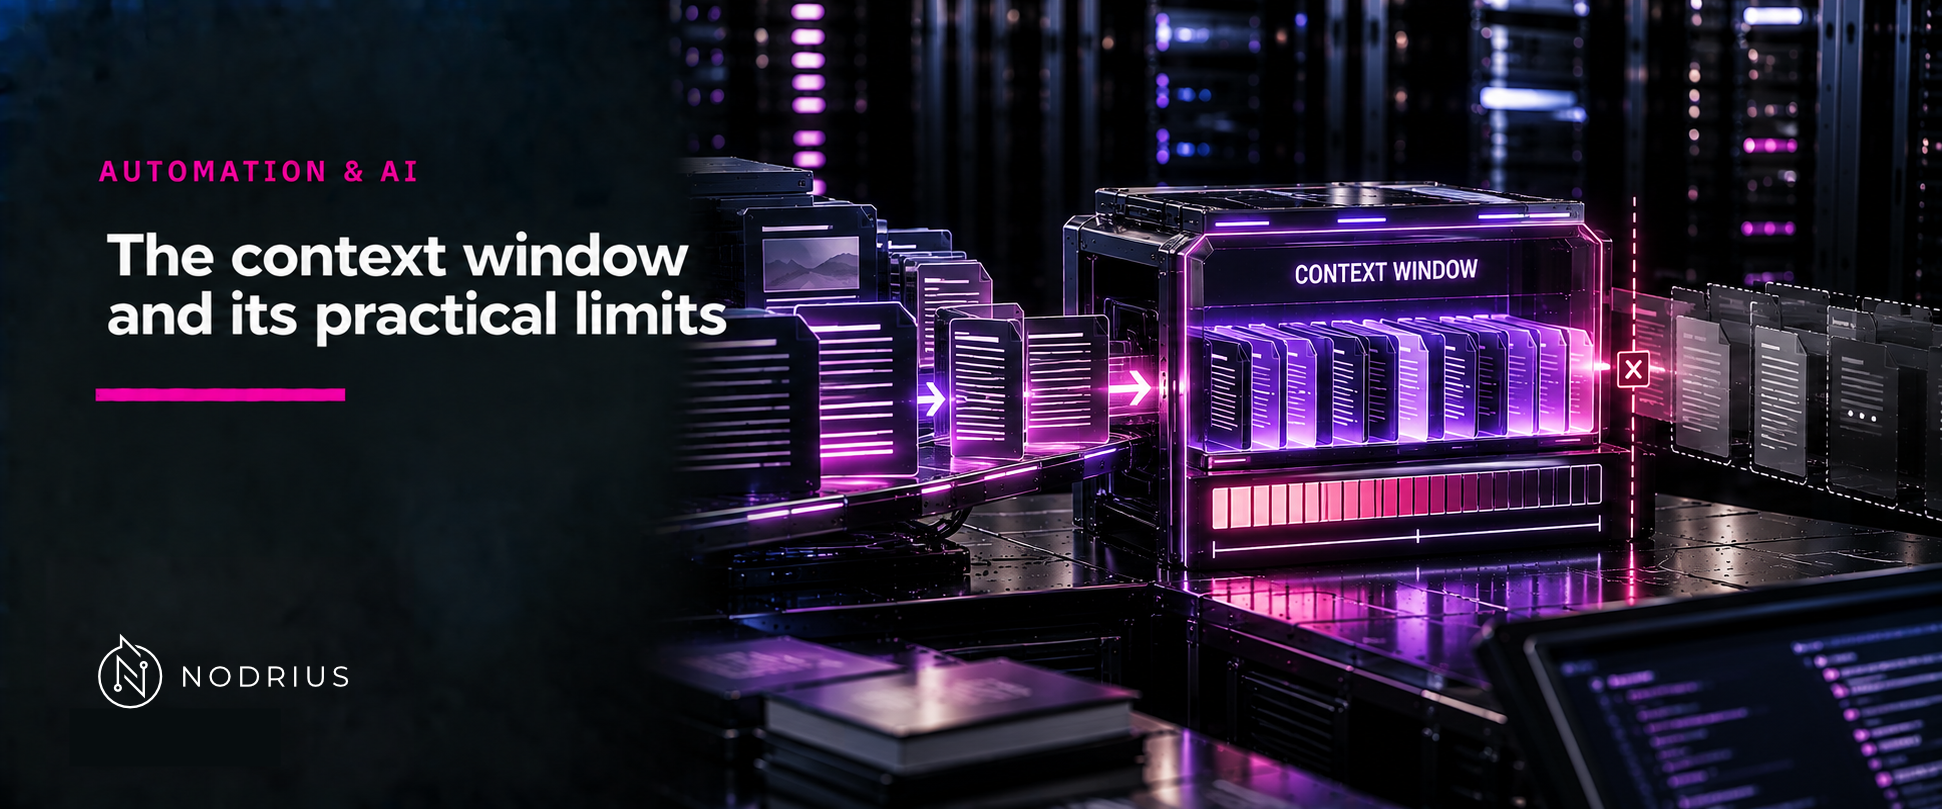
A shared token budget, not durable memory: what the window is and where it runs out.
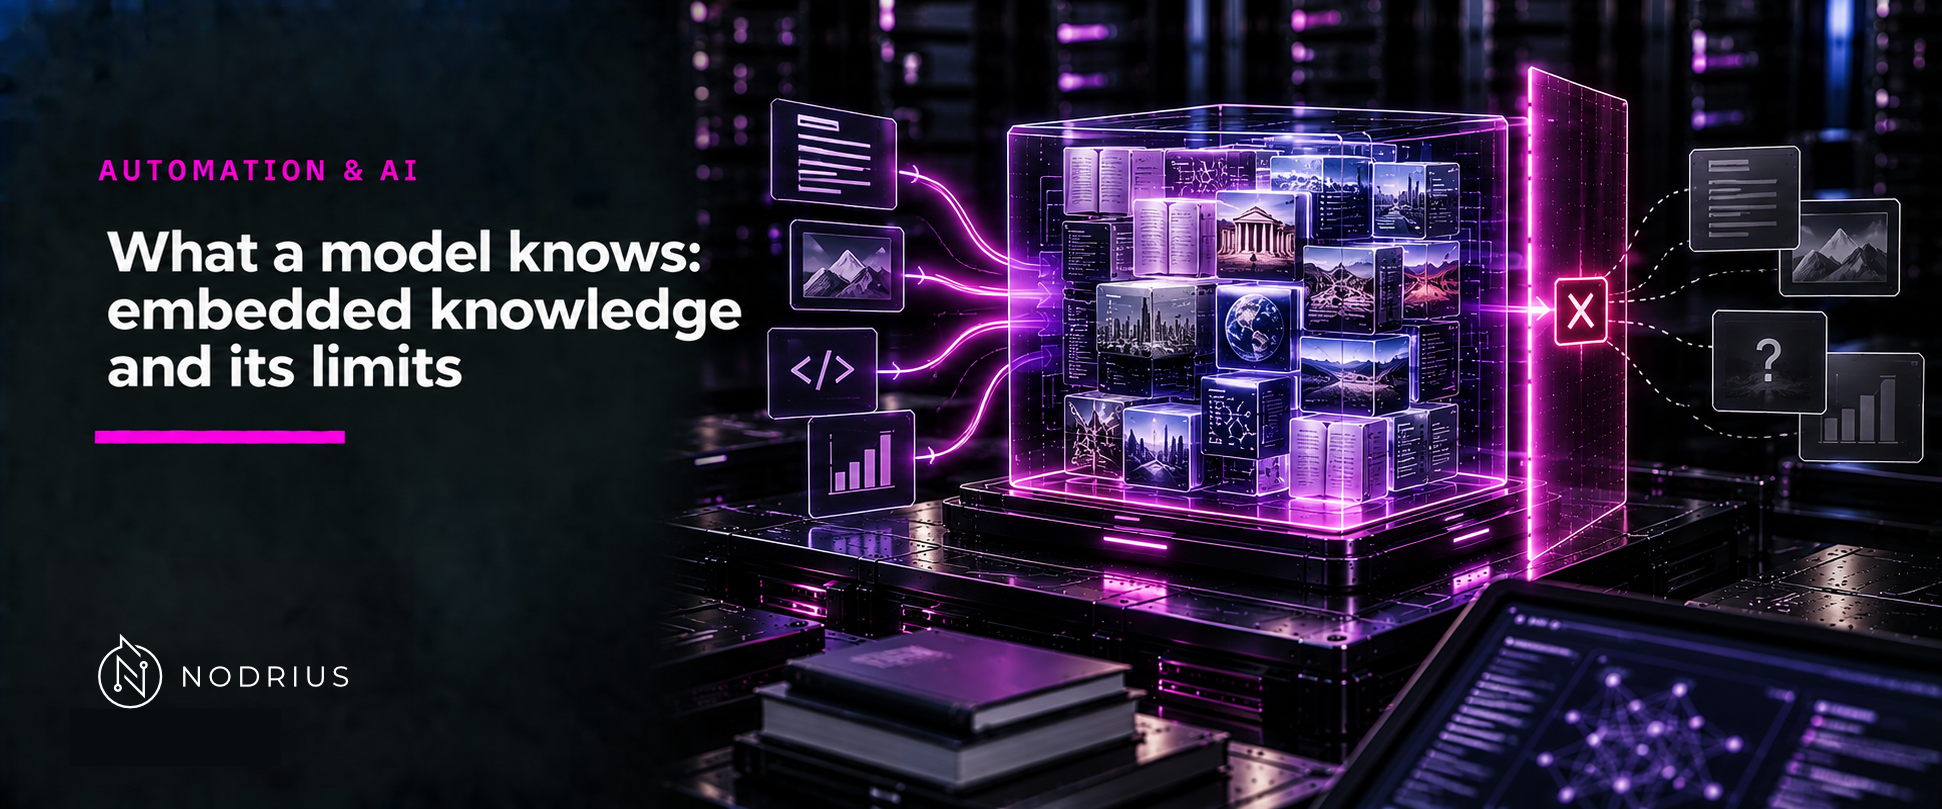
What sits in a model's parameters, what its training cutoff freezes, and what you supply.
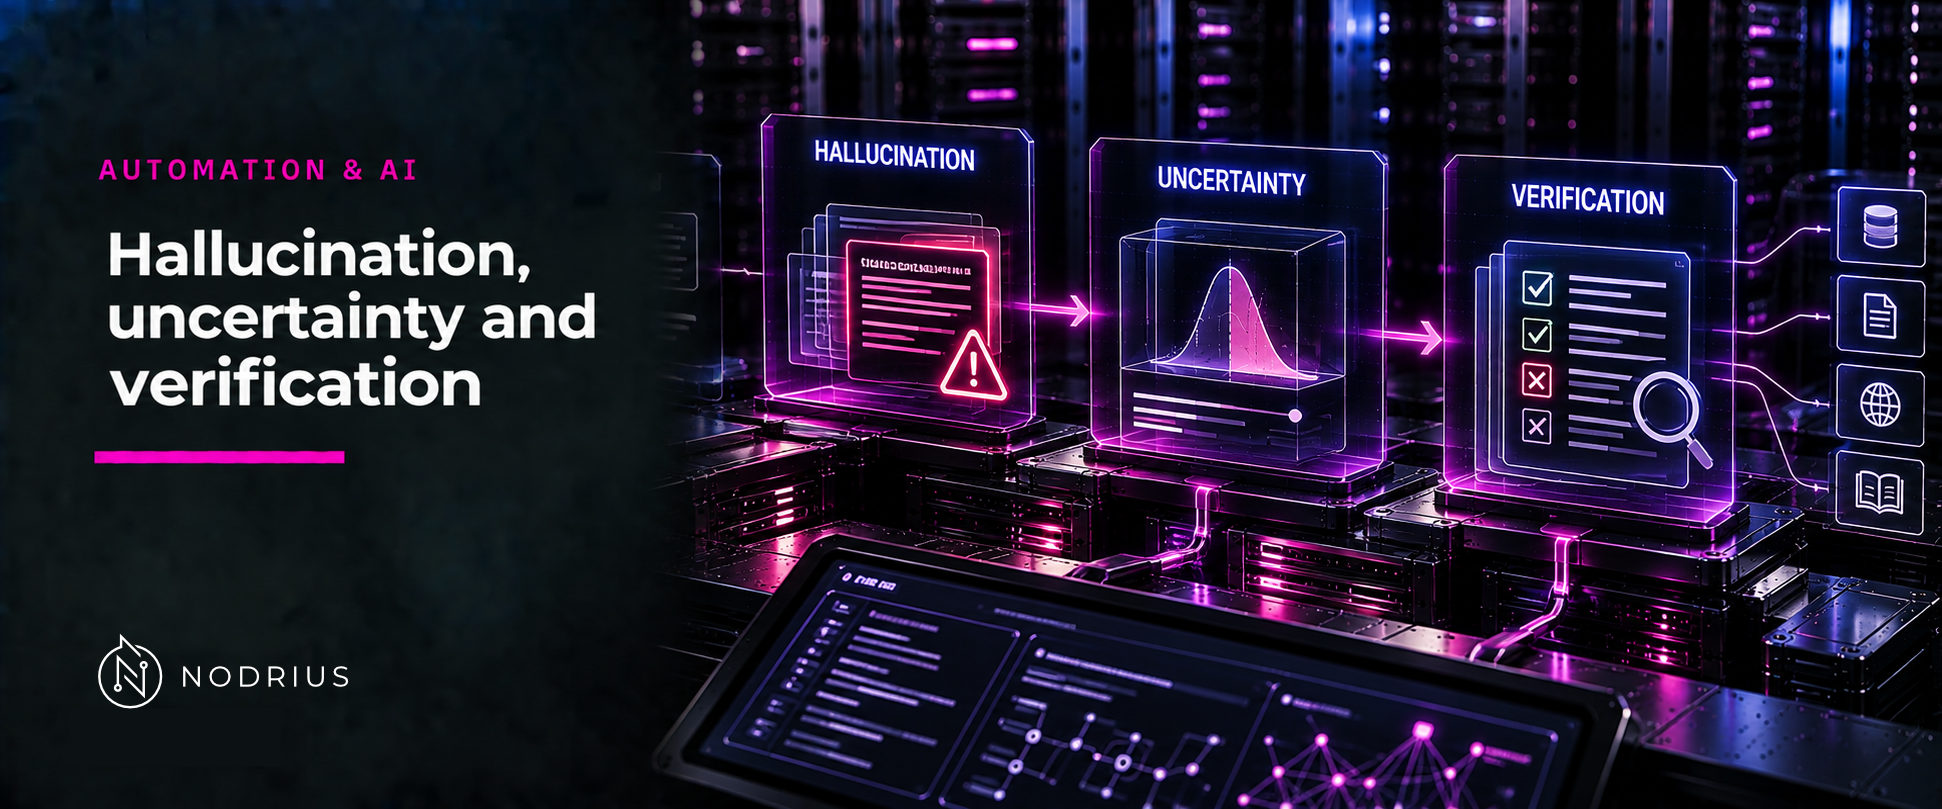
Why a fluent model answer can be false, and what checking it actually requires.
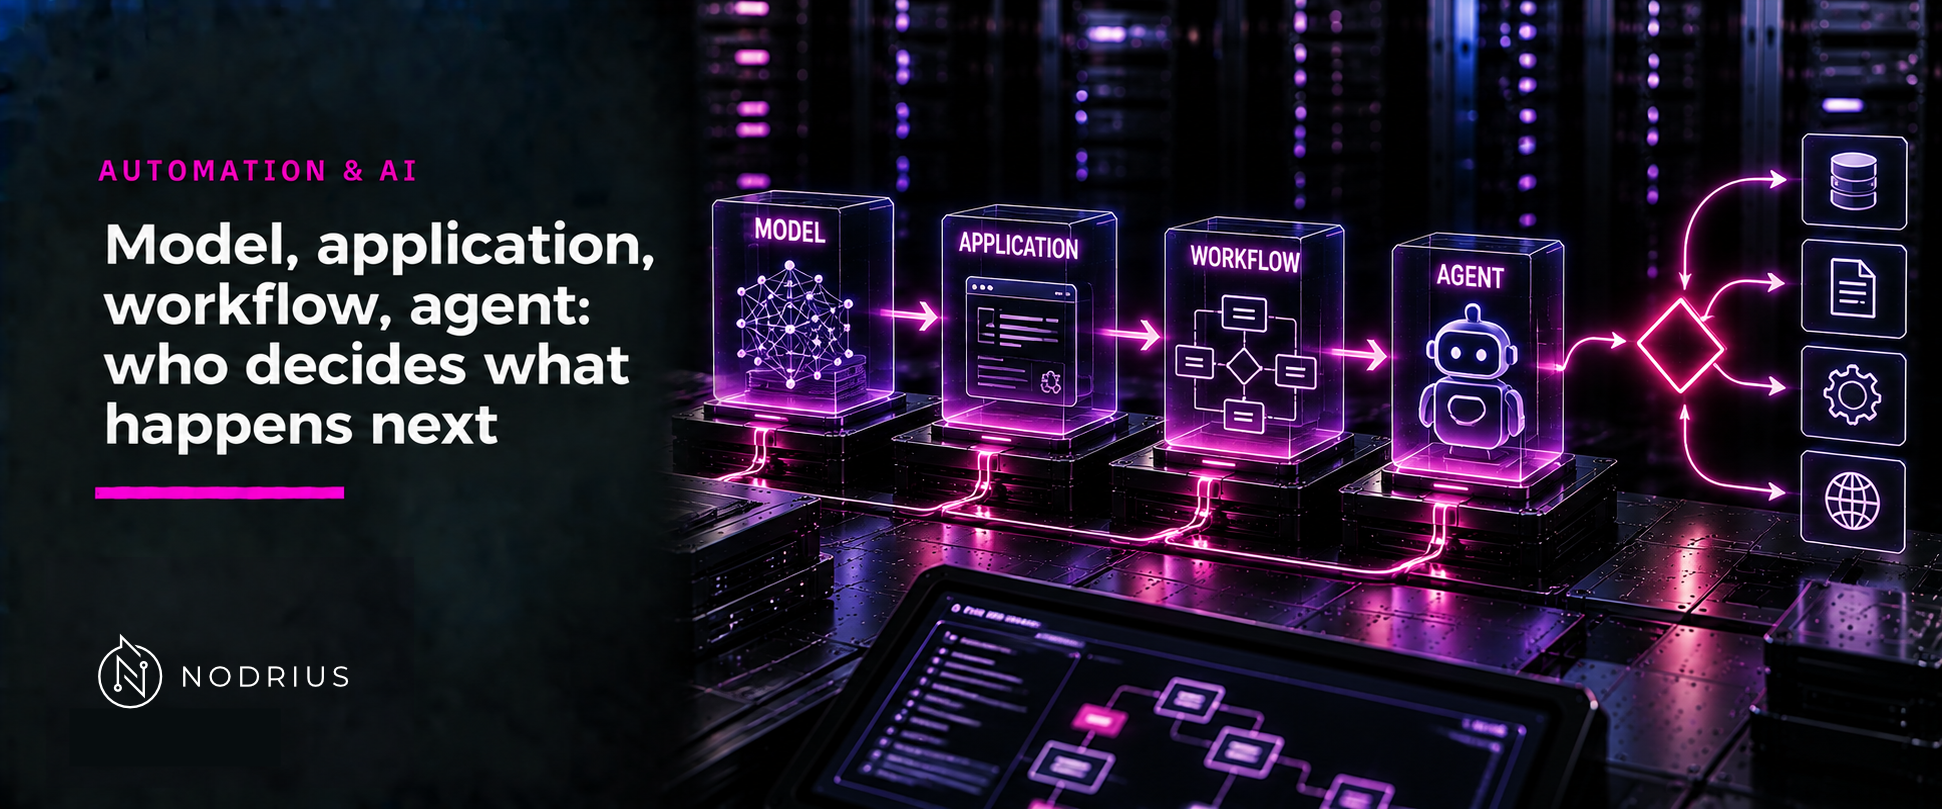
Who chooses the next step: the model, the application around it, a workflow or an agent.
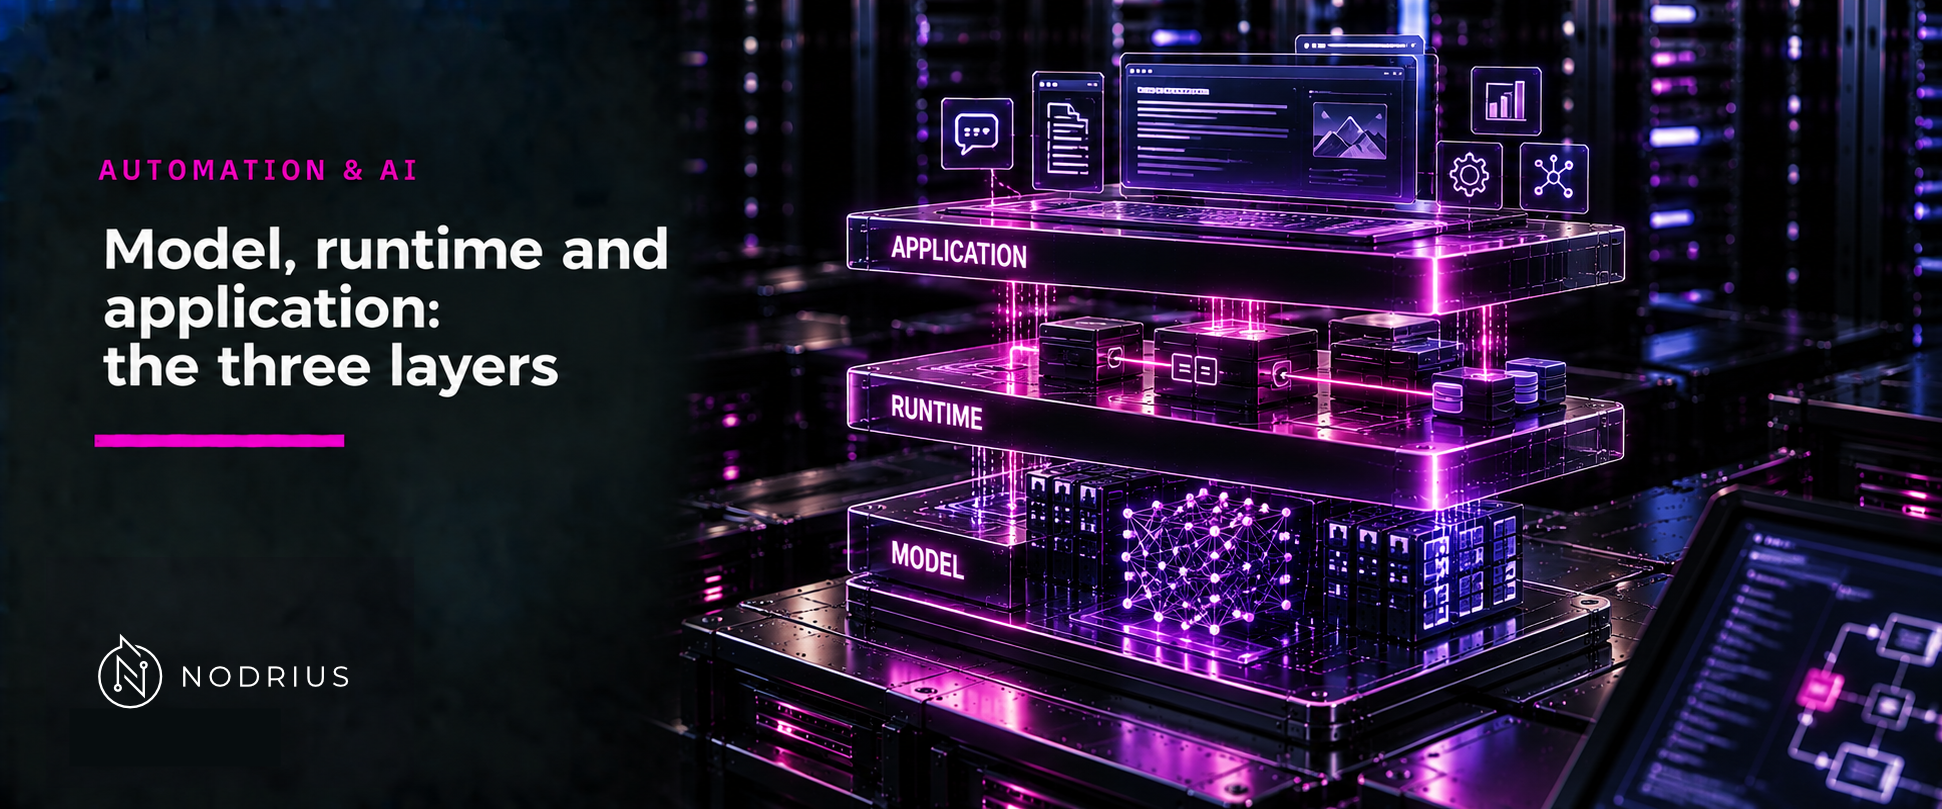
The model file, the engine that runs it, the product around it — and what a symptom means.
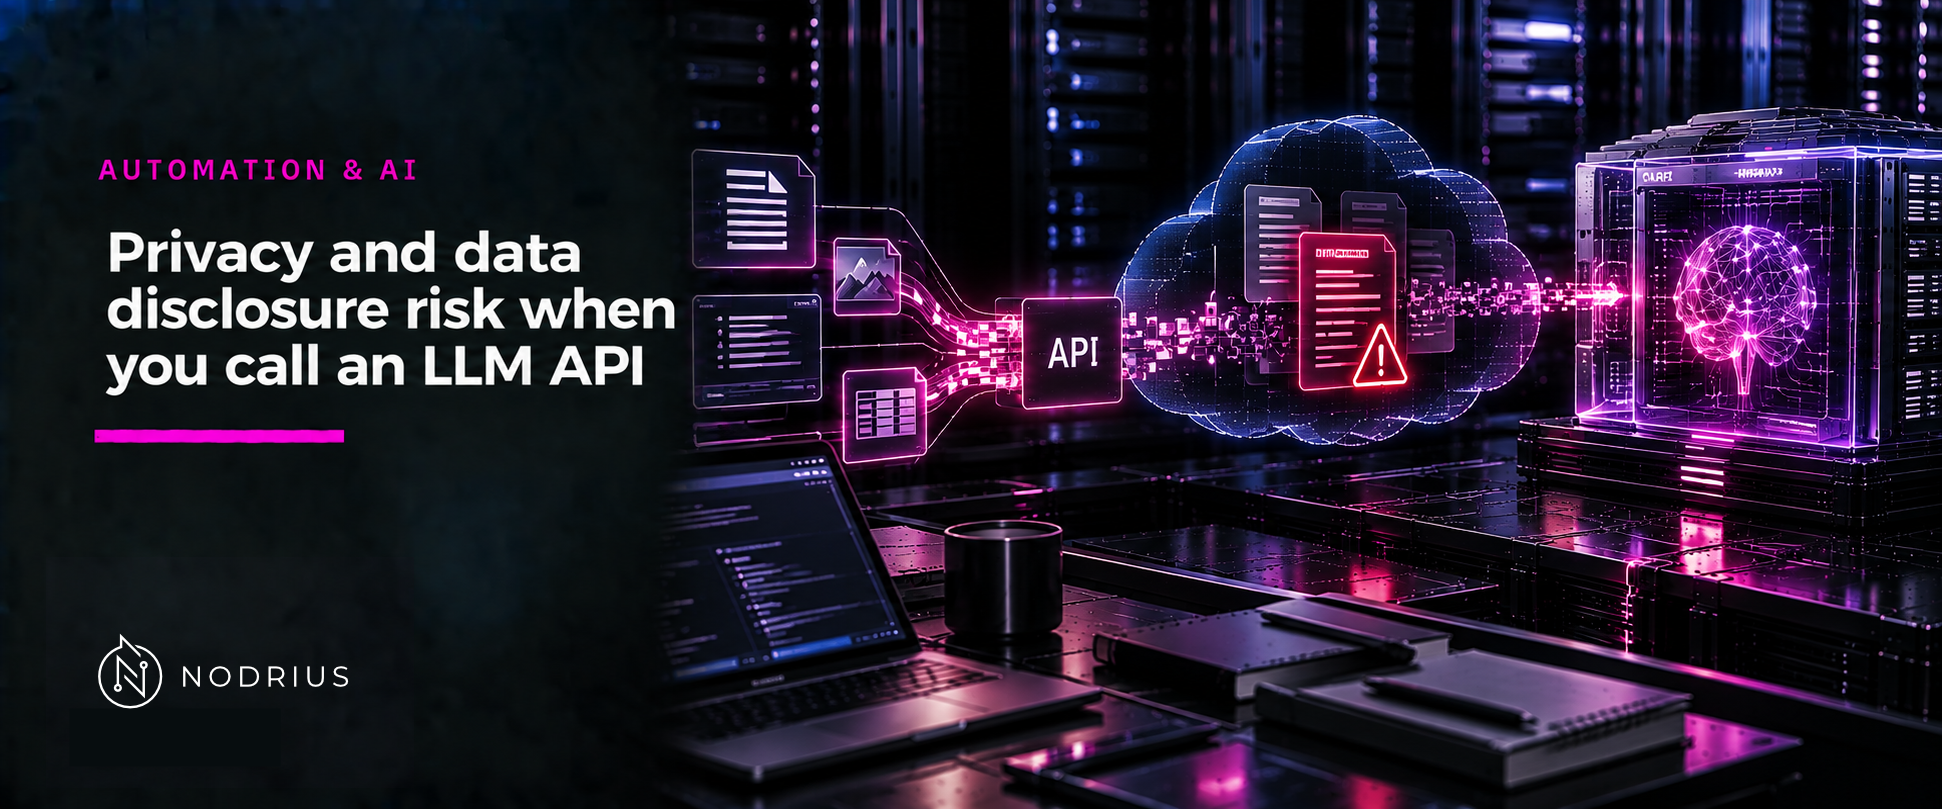
What leaves your machine on an API call, what may come back, and the rules that follow.
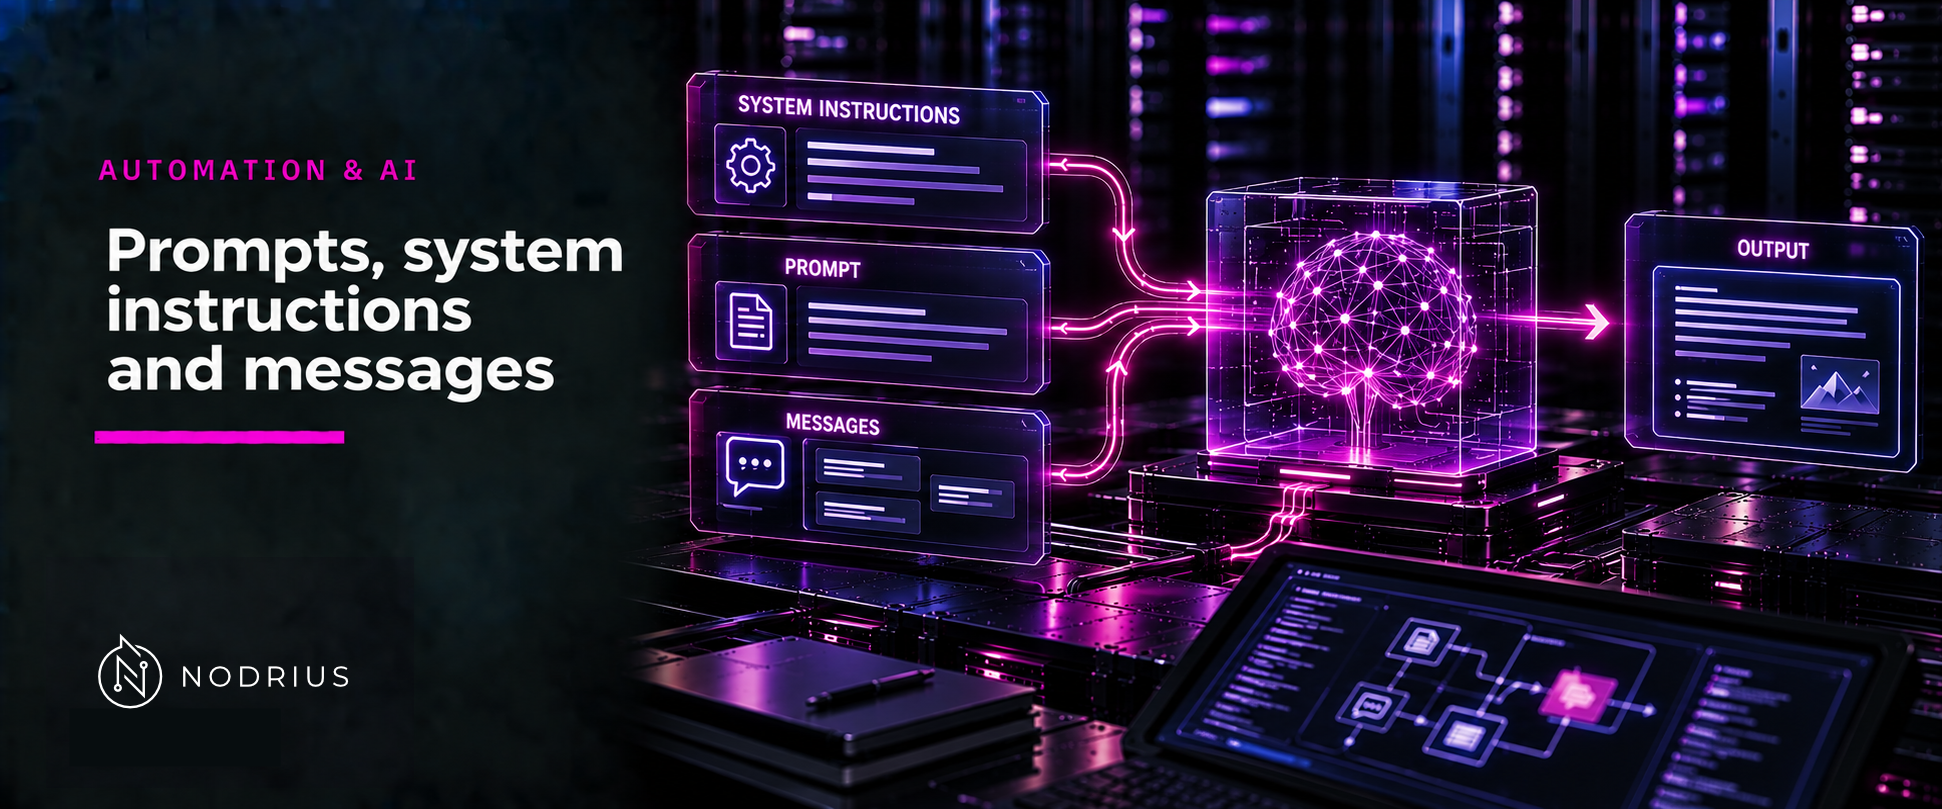
What a prompt and a system instruction are, and why an instruction is not a control.
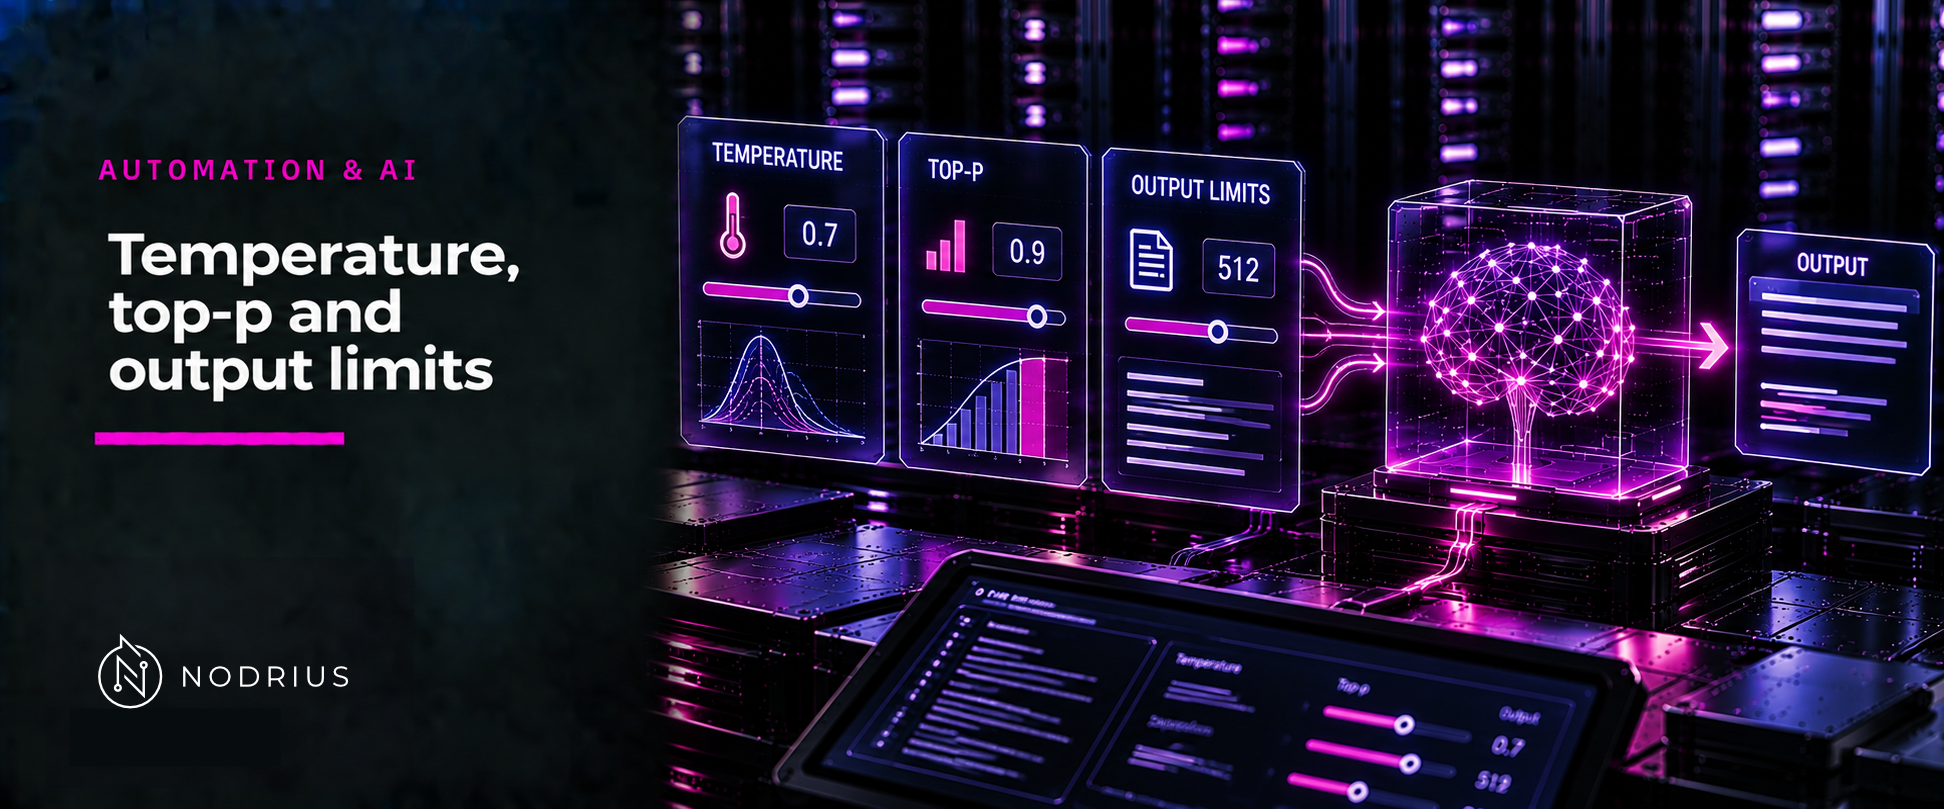
How one token is chosen out of a distribution, and what a token limit actually bounds.
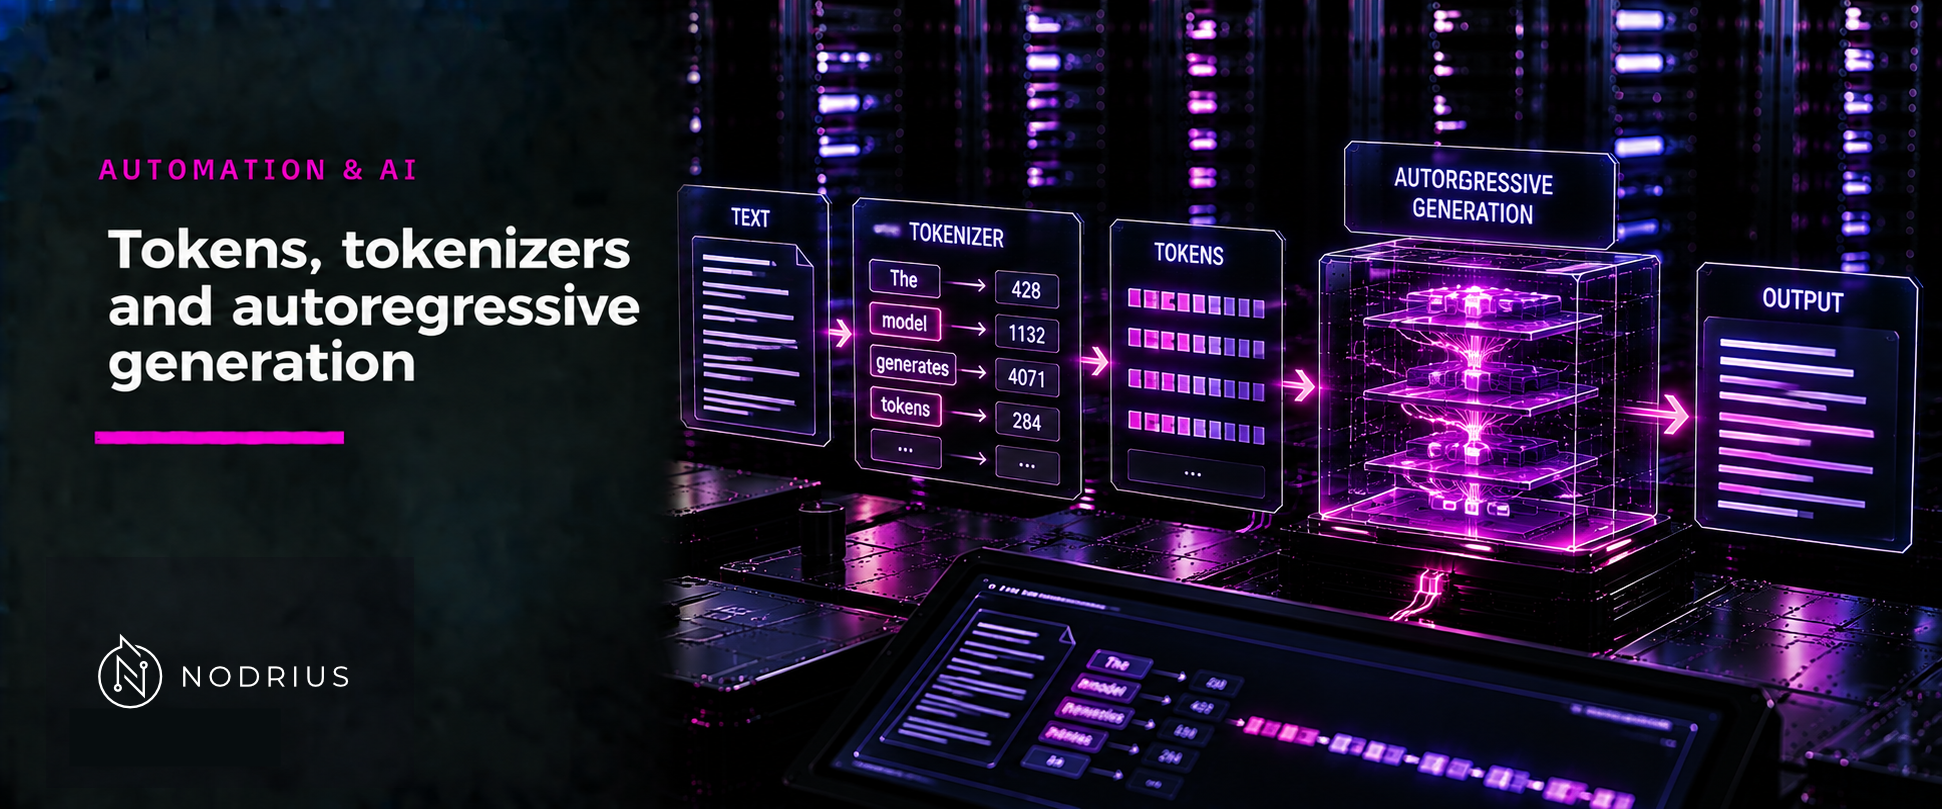
Why text becomes tokens, what a tokenizer and vocabulary are, and how generation works.