
Articles
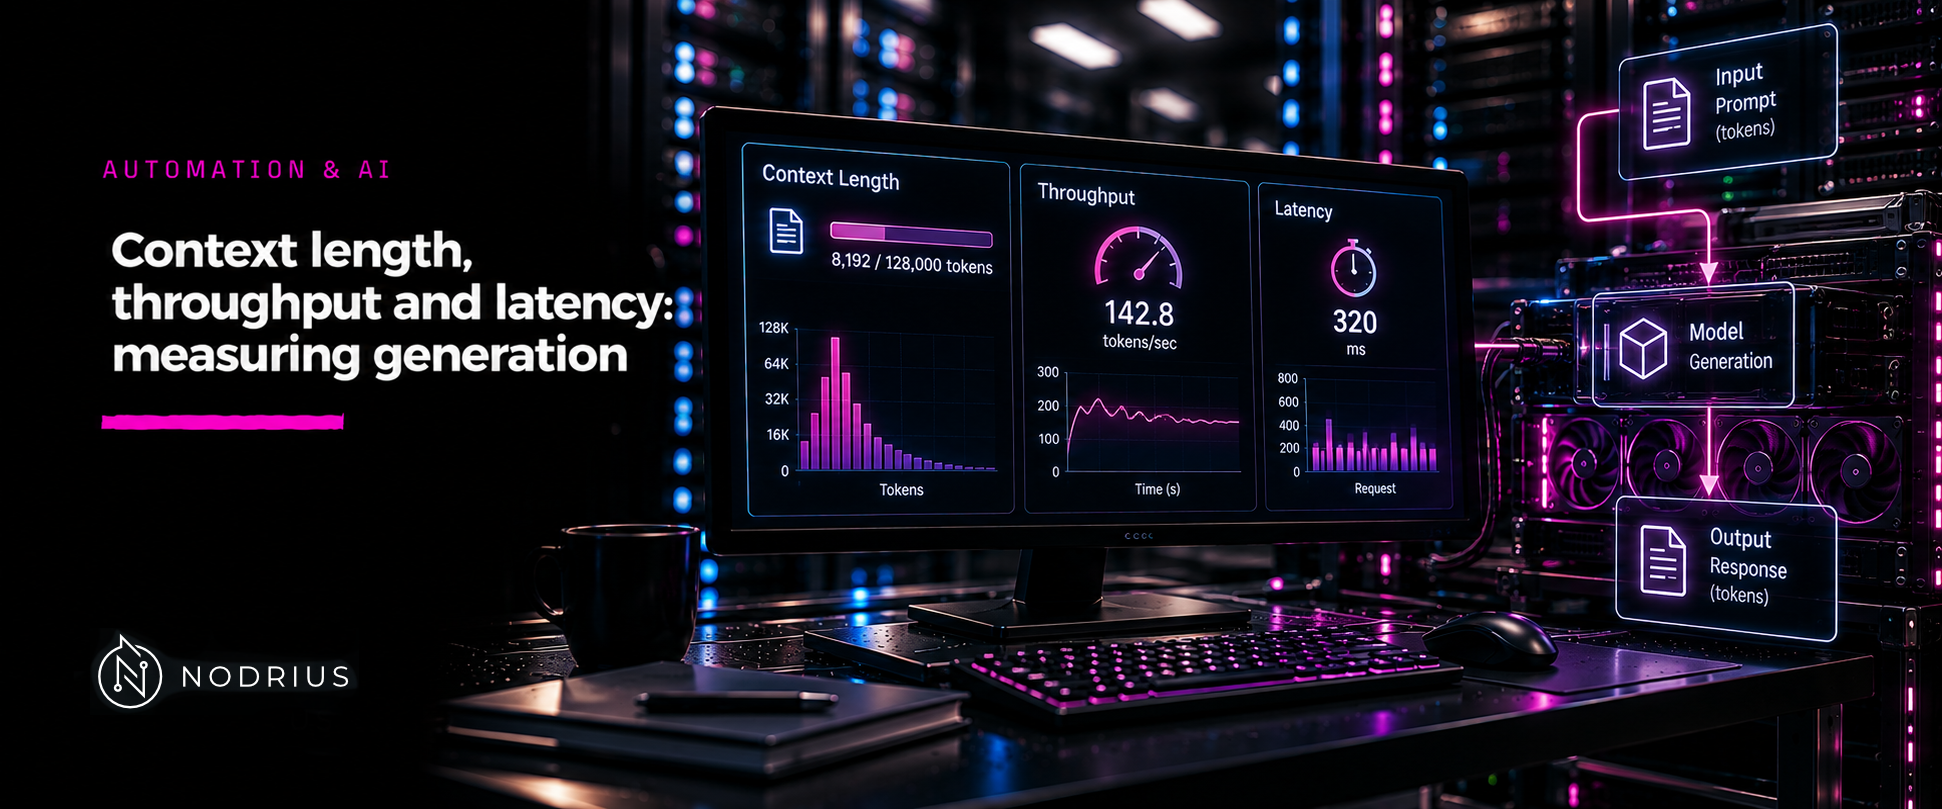
Context length, throughput and latency: measuring generation
Four numbers describe a generation; none of them means anything without its conditions.
Four numbers describe a generation; none of them means anything without its conditions.
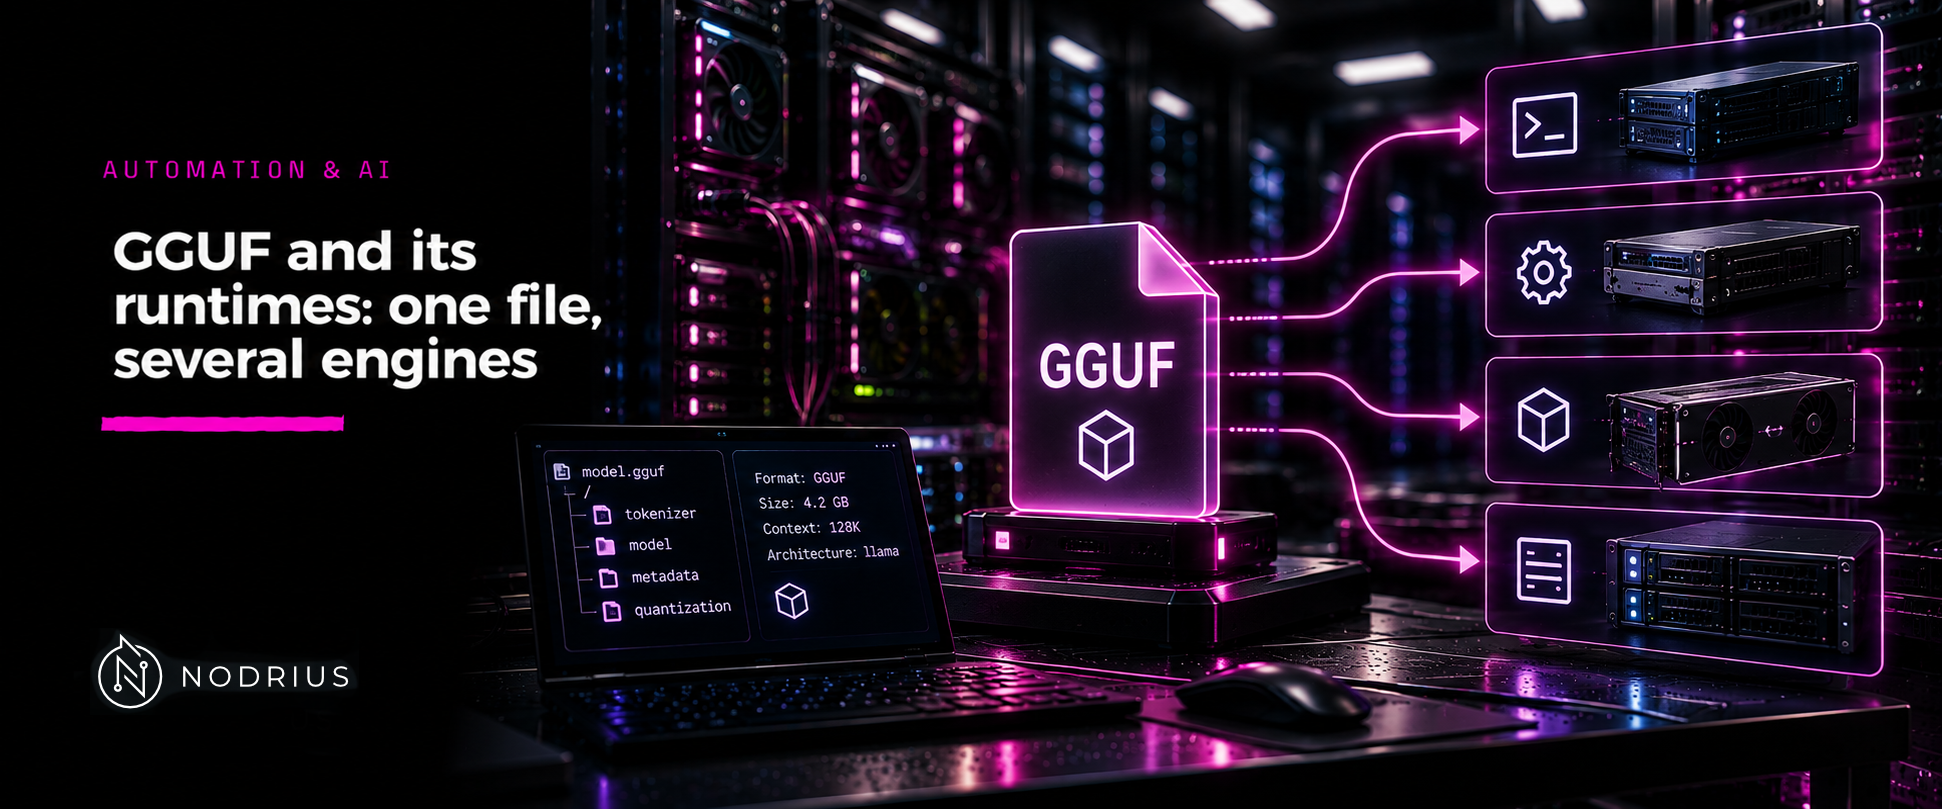
GGUF is a container; which engine reads it, and how, is a separate question.
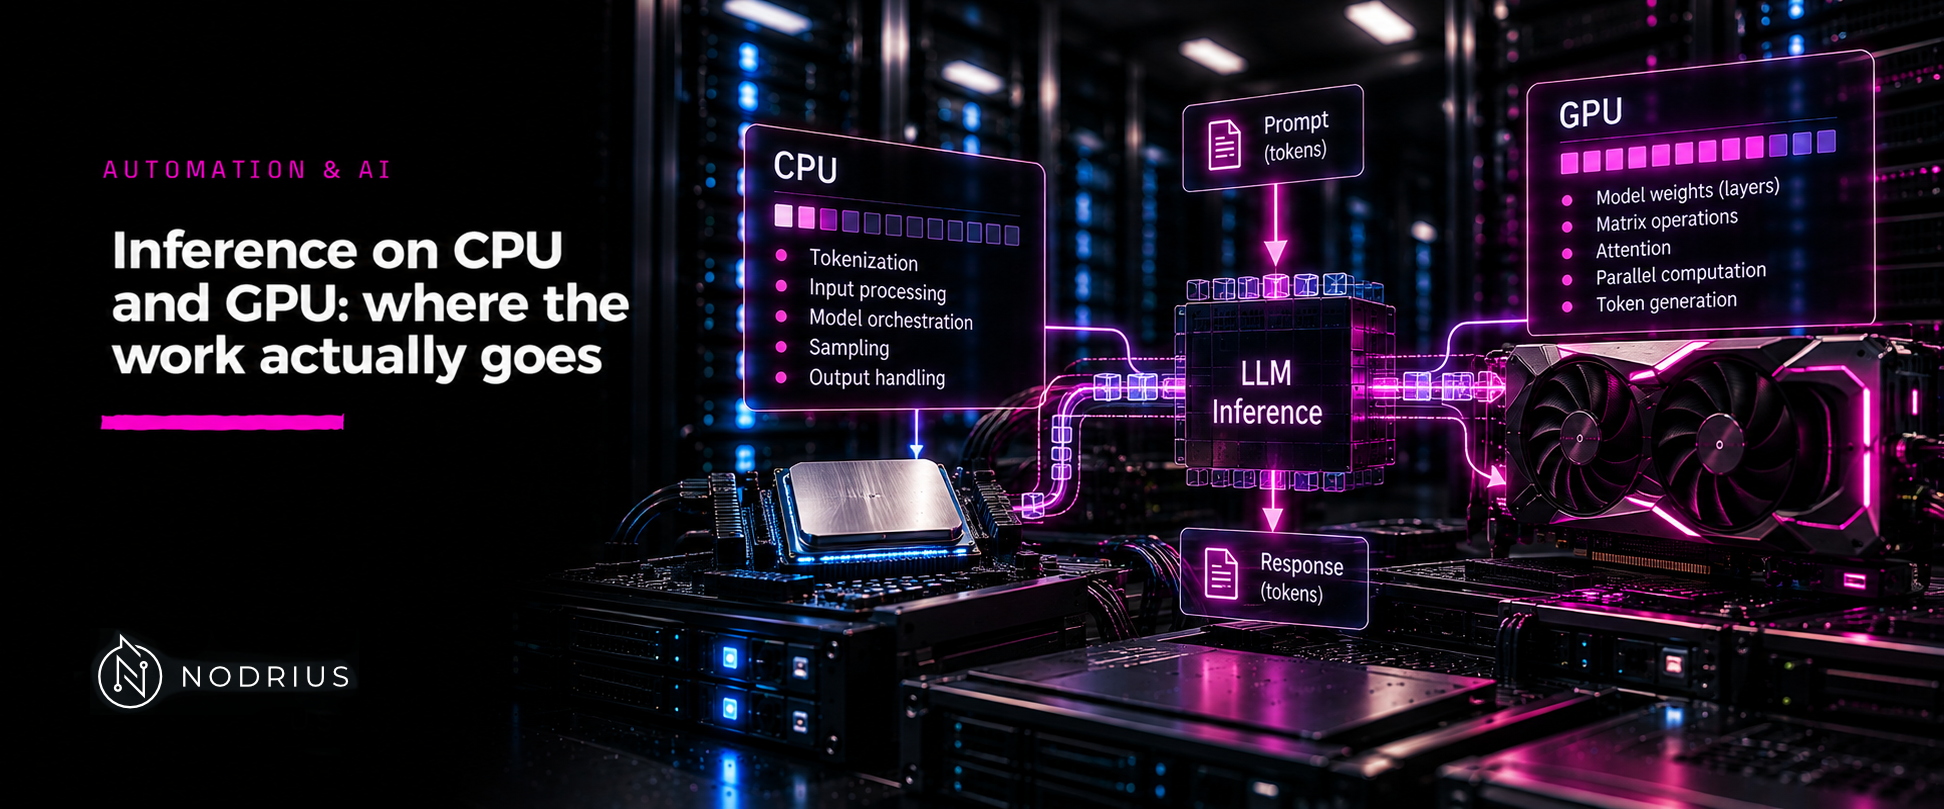
The same model runs on a CPU, a GPU or both; what changes is where the work is done.
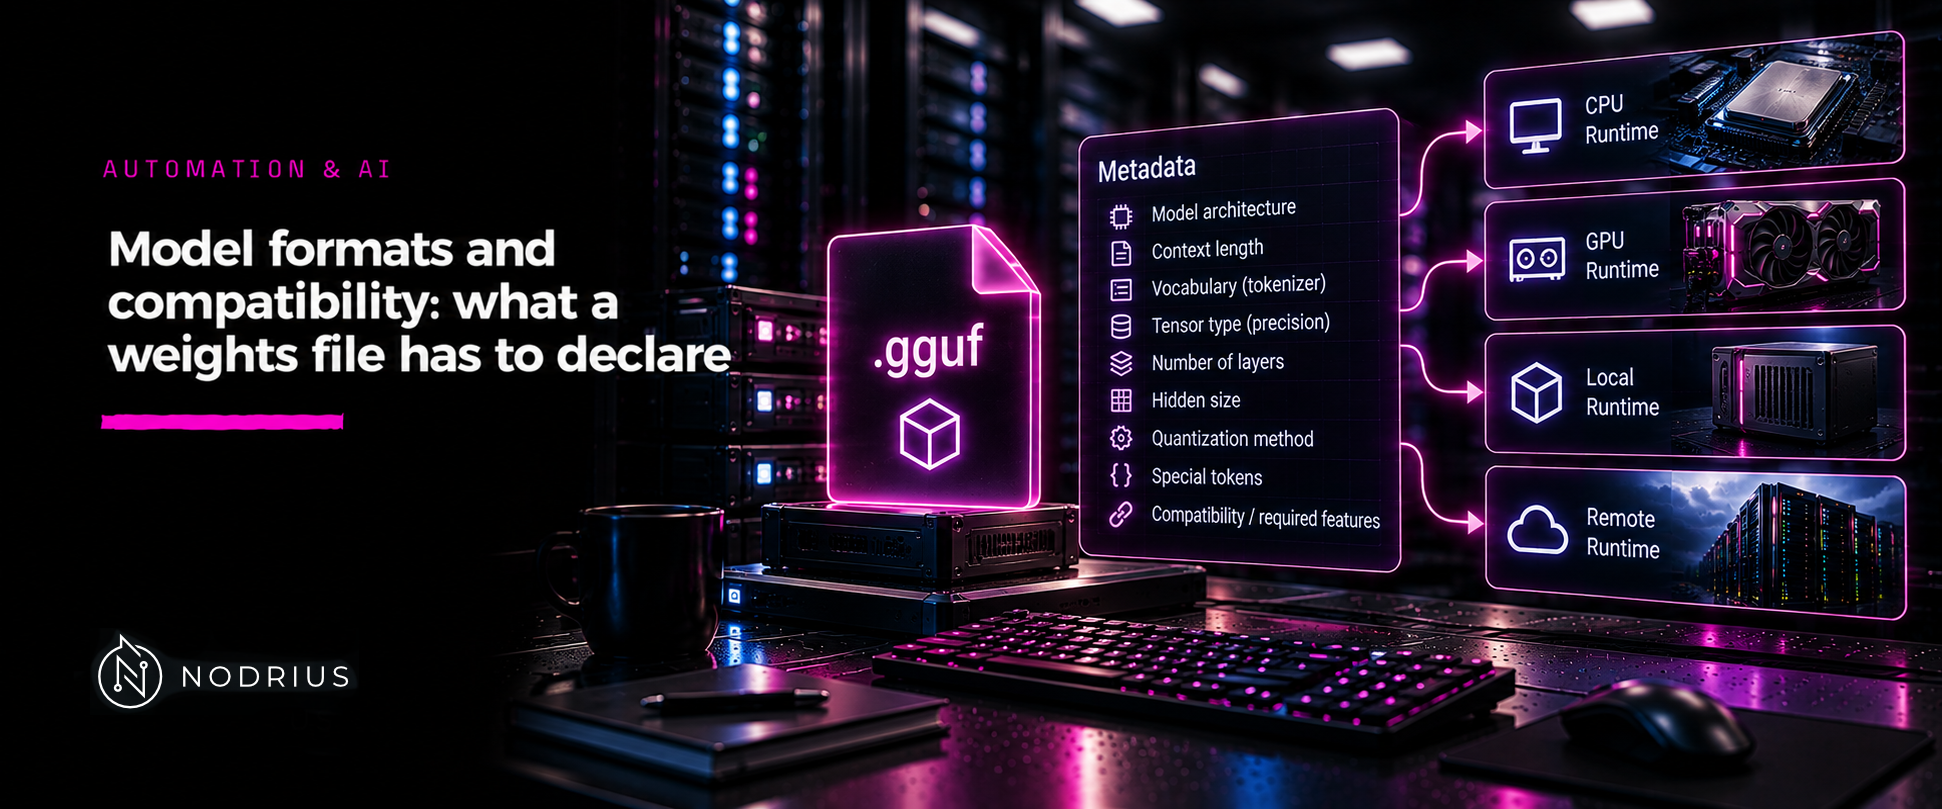
A weights file is not the model: format, architecture and tokenizer must all line up.
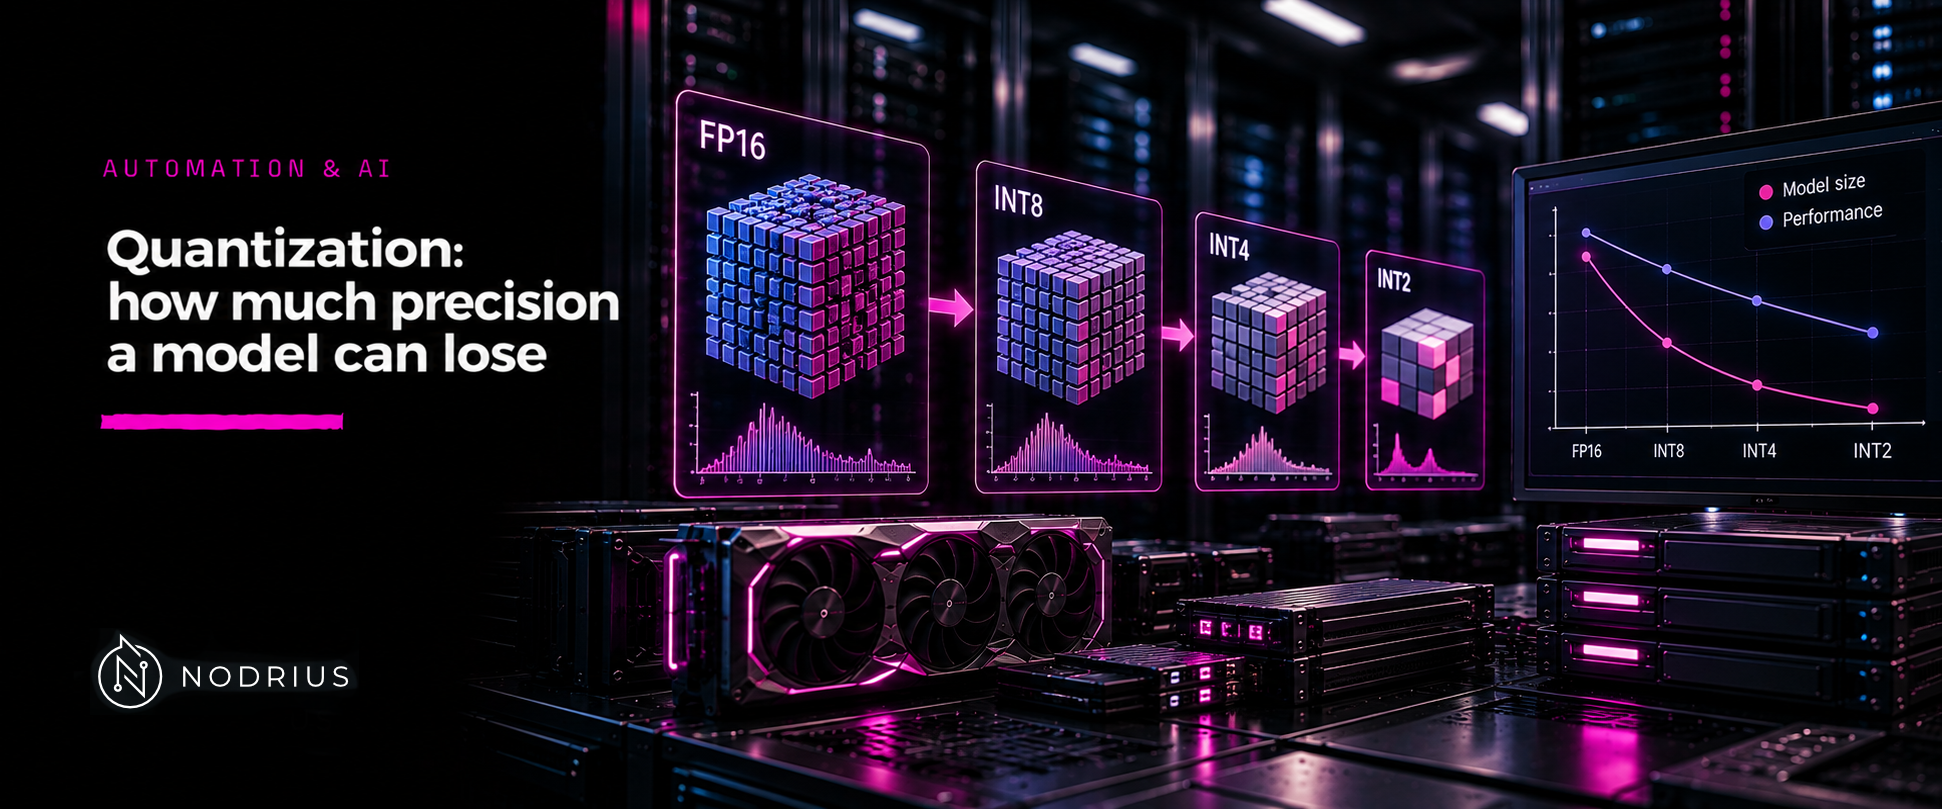
Fewer bits per weight save memory; what that costs in quality must be measured.
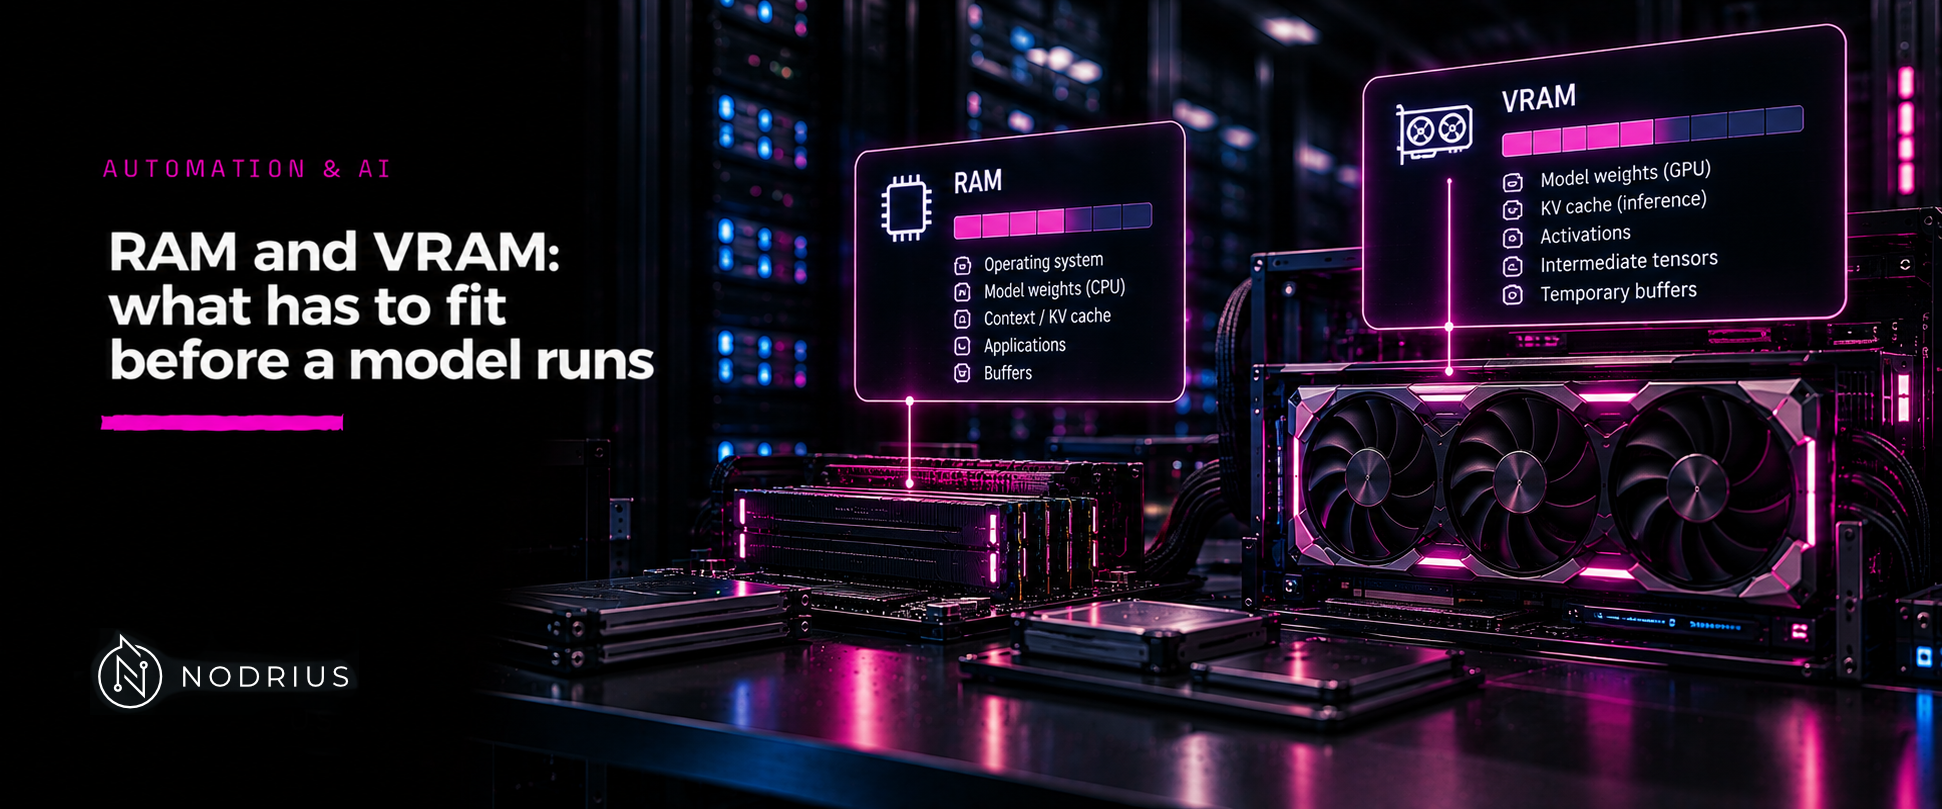
Weights, KV cache and working memory compete for the same pool; fit is arithmetic first.
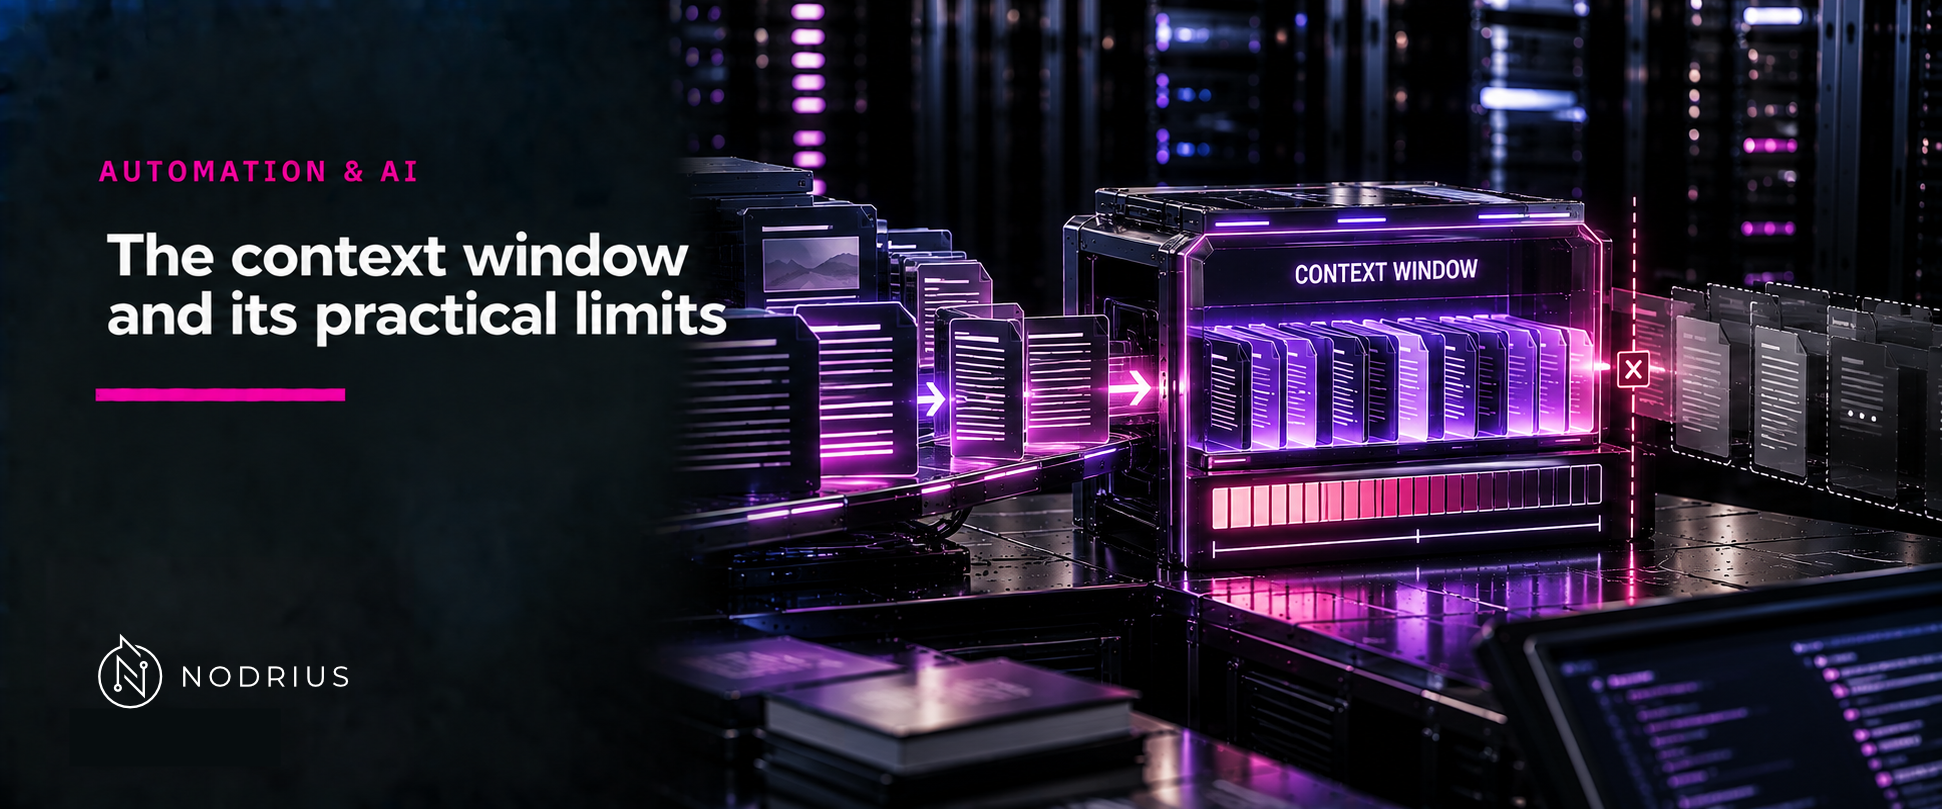
A shared token budget, not durable memory: what the window is and where it runs out.
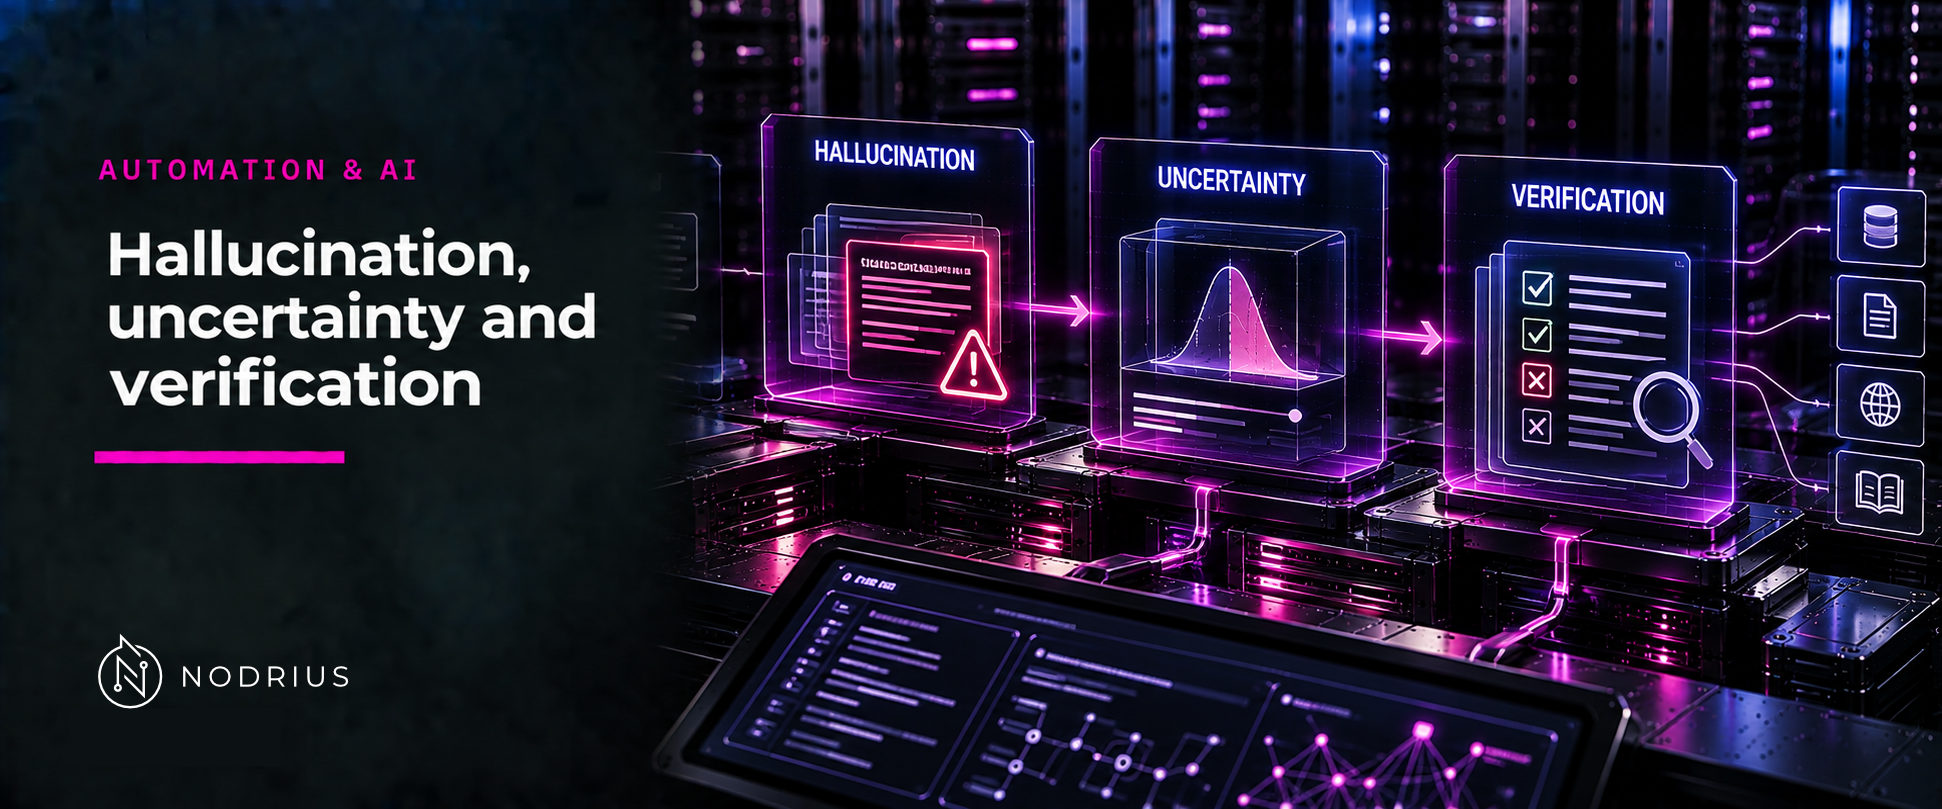
Why a fluent model answer can be false, and what checking it actually requires.
How one token is chosen out of a distribution, and what a token limit actually bounds.