
RAM and VRAM: what has to fit before a model runs
Weights, KV cache and working memory compete for the same pool; fit is arithmetic first.
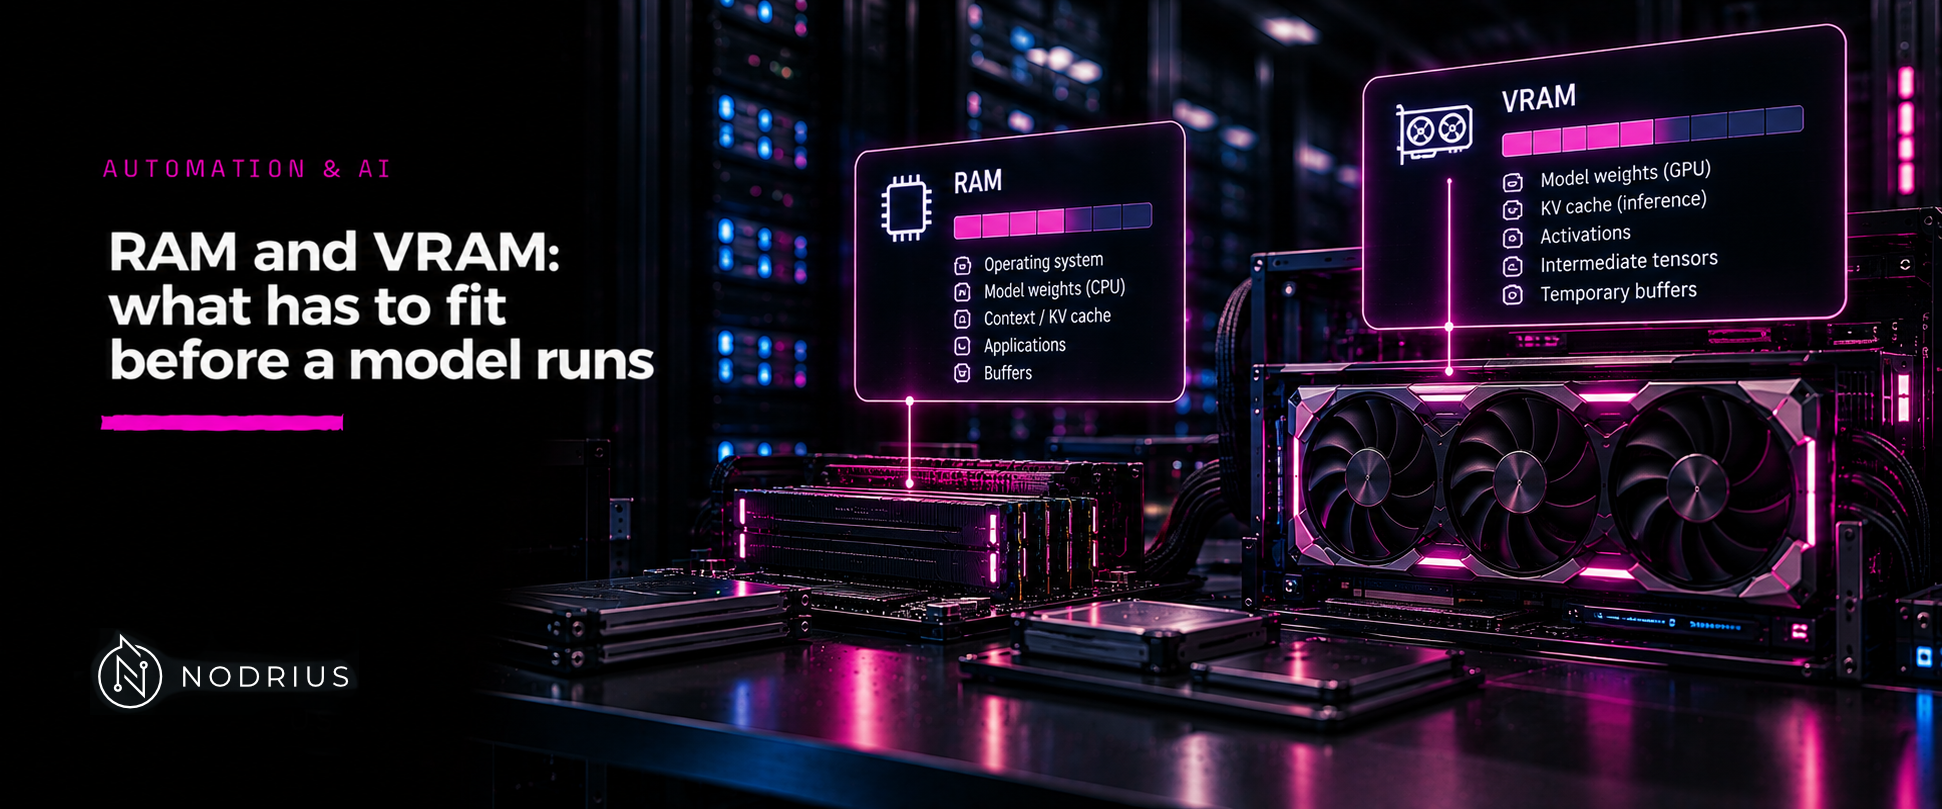
A weights file has a size; a running model has a footprint. Three things occupy memory at the same time — the weights, the cache that remembers what the model has already read, and the runtime’s own working memory — and only the first is visible before you press enter. That is why “it fits, it is a 7B model” is not an argument: the file may be the smallest of the three.
The weights: the predictable part
Weights cost their parameter count multiplied by the bytes each weight occupies: about two bytes at half precision, one at 8 bits, about half a byte at 4 bits. A 7-billion-parameter model therefore sits near 14 GB in its standard form, 7 GB at 8 bits and 3.5 GB at 4 bits — arithmetic on the file format, not a measurement, and the reason quantization is the first tool for making something fit.
The cache: the part that grows while you work
Every generated token makes the model keep the attention keys and values of everything before it. The vLLM paper describes the consequence as a serving problem: the key-value cache’s “memory for each request is huge” and grows and shrinks while the server works; managed inefficiently, that memory is wasted by fragmentation and redundant duplication, which limits the batch size. Its own illustration of serving a 13-billion-parameter model on a 40 GB accelerator shows the parameters taking 26 GB (65 per cent) and the KV cache more than 30 per cent — a cache that is not a rounding error next to the weights, and that can exceed them at long contexts or with several requests in flight.
The cache has a precision of its own. A llama.cpp server defaults the cache to f16 for both K and V and
accepts q8_0, q4_0, q4_1, iq4_nl, q5_0 and q5_1 — the same memory-for-precision trade as weight
quantization, applied to a tensor that grows at runtime rather than to one that sits on disk.
How large it becomes depends on how much text it holds (context length), how many requests share the pool, the cache’s data type, and the model’s own architecture. None of those is in the file size.
The engine’s share, and the waste
Not all of the memory you think you have is available to hold those two things. The vLLM authors report that in the systems they measured, “existing systems waste 60% – 80% of memory due to fragmentation and over-reservation”, and that their own allocation strategy brings the waste down to “under 4%”. Whether a given engine can use 80 per cent of the device or half of it is therefore part of the question, and it is the reason two engines can fail at the same context length on the same card.
Training figures are not inference figures
Half-precision training is often quoted as a sizing rule, and it is the wrong one. Training holds the weights, a second copy for stable updates, optimizer state and gradients — the vendor documentation’s own accounting is six bytes per parameter for the weights, eight more for Adam’s momentum and variance, four for gradients in fp32, plus activations that “vary in size with batch size, sequence length, model depth and hidden size” — which is why “training a 4B parameter model in mixed precision on a batch size of 16 requires roughly 85GB of GPU memory”. Inference keeps none of the optimizer or gradient tensors. Reusing the training number overestimates the requirement; ignoring the cache underestimates it.
The knobs that move the footprint
In a llama.cpp server, the parameters that decide where the weights live and how large the cache may grow are explicit:
-ngl, --gpu-layers: “max. number of layers to store in VRAM, either an exact number, ‘auto’, or ‘all’” — layers not offloaded stay in system RAM.-ts, --tensor-splitand-sm, --split-mode {none,layer,row,tensor}— how a model is divided across more than one GPU.-c, --ctx-size— the prompt-context size, whose default of 0 means “loaded from model”; this and the cache data type set the cache’s ceiling.-np, --parallel(server slots) and--kv-unified-per-slot, which sets a “context limit per parallel slot” — concurrency is a memory decision, not only a throughput one.-cmoe, --cpu-moeand-ncmoe— keeping expert weights on the CPU, which is a placement decision of a different kind from offloading layers.-b, --batch-sizeand-ub, --ubatch-size— batch sizes that shape the working memory used while processing.
None of this is engine-specific in principle: every engine has an equivalent set, because the same three things have to fit.
Where the failure appears
Out of memory is not one event. At load time it is the weights that do not fit — and that failure is immediate and unambiguous. During generation it is the cache that has grown past the pool, and the symptom is a request that fails after the prompt was accepted, or a server that refuses new slots while the ones it has are full. An estimate tells you what to try; the engine’s own reporting of the memory it has reserved is what tells you whether it worked.
Level and prerequisites. L2 — operational: the reader must be able to break a footprint into weights, cache and overhead, and to know which engine parameter moves each part. The formula for a given architecture’s cache is deliberately not given here; this sheet names the inputs, and sizing a specific deployment is a Progetti task. Prerequisites: the quantization and formats sheets of this batch.
Where to go next
- Automation & AI — the macro-area this sheet belongs to.
- Model behaviour — the node this sheet sits in.
References
- vLLM — paper and blog post — the KV cache as the memory that grows and shrinks, the 13B/40 GB memory breakdown, and the 60–80 per cent waste figure.
- Hugging Face — GPU memory usage — the per-parameter accounting for training and the activations caveat.
- ggml-org — llama.cpp server —
--gpu-layers,--tensor-split,--split-mode,--ctx-size,--parallel,--kv-unified-per-slot, cache data types, MoE placement, batch sizes. - ggml-org — llama.cpp README — CPU+GPU hybrid inference as the documented way to run a model larger than the available VRAM.